Whamit!

The Weekly Newsletter of MIT Linguistics

Search Results

Call for abstracts: Morris Halle Centenary Conference


Dates: September 8-10, 2023
Location: MIT, Cambridge, MA, USA
Meeting Email: m100@mit.edu
Conference website: http://m100.mit.edu/index.html
Linguistic Fields: Phonology and Morphology
Abstract Deadline: May 25, 2023
 
Meeting Description:
To mark the centenary of Morris Halle’s birth, MIT will host a conference, Morris at 100, on September 8–10, 2023. The conference will consist of contributed posters grouped thematically into sessions on the following topics: evaluation metrics, distinctive features, morphology and the lexicon, rules and rule ordering, stress and meter. Each poster session will begin with an introduction to its theme, in relation to Morris Halle’s work. After each session, there will be a general discussion of the posters in it.
 
Call for Papers:
  • We invite abstracts for poster presentations on the session topics above: evaluation metrics, distinctive features, morphology and the lexicon, rules and rule ordering, stress and meter. The posters need not be about Halle’s contribution to any of these topics, though such submissions are welcome. Whether connected to Halle’s work or not, we hope the posters will report new results bearing on the conference topics.
  • Abstracts must be anonymous. Length is limited to two single-spaced pages (US Letter), figures and references included. Font size should be at least 11-point, with margins of at least one inch (2.54cm) on all sides. Abstracts must be submitted in .pdf format. Submissions are limited to two per author, with at most one submission being single- or primary-authored. More information here: http://m100.mit.edu/callforposters.html.
  • The deadline for abstract submission is May 25, 2023 at 11:59 p.m(EDT). Abstract submission is open as of March 30, 2023. Submission should be made via EasyChair:
 
Questions about submissions should be addressed to m100@mit.edu .
 
Important dates:
Abstract deadline: May 25, 2023
Notification of acceptance: June 15, 2023
Program published: August 1, 2023
Conference: September 8–10, 2023
 

Syntax Square 4/4 - Zachary Satoshi Feldcamp (MIT)

Speaker: Zachary Satoshi Feldcamp (MIT)
Title: Predicate inversion as A-movement
Time: Tuesday, April 4th, 1pm - 2pm

Abstract: Predicate inversion (PI) constructions (1) involve a marked order of constituents in which the predicate (underlined) appears to occupy the typical derived subject position, and the would-be subject (italicized), which often receives the nuclear pitch accent and focus, occurs to the right of the auxiliary be (Emonds 1970; 1976; Birner & Ward 1998; Samko 2016; Thoms & Walkden 2019).

(1) Performing at the concert next month will be SAM.

The absence of weak cross-over effects and of reconstruction for Condition C suggests that the predicate undergoes A-movement, which is initially puzzling, given what is known about A-movement, locality, and the interpretation of moved predicates, additionally raising questions about the possible role of information-structure in syntactic derivations. Contra Samko (2014; 2016), I argue that PI is not driven by information-structural features, because it is not subject to any firm information-structural conditions.

I propose that PI is the result of T agreeing with the predicate instead of the would-be subject, possible whenever the predicate has (incomplete) φ-features valued via concord with the would-be subject. No locality issues arise, because both subject and predicate may move in a nesting configuration to specifiers of Aux be, which position can be directly observed in passive expletive constructions (Rezac 2006). Given the cross-linguistic generalization that non-nominal lexical categories do not bear person features, the analysis predicts that T, which has agreed with the predicate, lacks person in PI. I show that this prediction is borne out. Despite its unusual appearance, then, PI corroborates the hypothesis that A-movement is the reflex of φ-Agree (van Urk 2015).

Phonology Circle 4/3 - Mirella L. Blum (University of Edinburgh)

Speaker: Mirella L. Blum (University of Edinburgh)
Title: Correspondence and variation in Dinka tone
Time: Monday, April 3rd, 5pm - 6:30pm

Abstract: This talk examines tonal phonology across dialects of the Dinka language (West Nilotic, South Sudan). Dinka has a highly complex sound system, with a three-level vowel length contrast, a voice quality contrast, and tone; all elements are both lexical and grammatical, and most of the language’s morphology is expressed through its suprasegmentals. Along with the high functional load of tone and extensive tone sandhi, the varying number of tones— dialects of Dinka have either three or four tones—has led to the impression that the tone systems of different varieties of Dinka cannot be compared, and that systematic correspondences do not exist. In contrast, I show how tones correspond across dialects of Dinka, depending in part on the vowel grade system—alternations of vowel quality and length pervasive throughout numerous areas of Dinka morphology. I show that dialects likely shift from four to three tones, not the other way around, and I discuss the range of tonal processes across dialects of Dinka, how the processes relate to one another, and how they hint at the evolution of the tone systems of individual dialects.

LingLunch 4/6 - Mitya Privoznov (MIT)

Speaker: Mitya Privoznov (MIT)
Title: The syntax of presupposition projection
Time: Thursday, April 6th, 12:30pm - 2pm

Abstract: Consider the following pair of sentences:

(1) Context: I don’t know whether Rosa ever smoked or not.
a. #But I don’t think that [she stopped smoking altogether] and [she used to smoke Belomor].
b. But I don’t think that [she used to smoke Belomor] and [stopped smoking altogether].

The sentence in (1a) sounds infelicitous in the given context, while the sentence in (1b) does not, see Mandelkern et al. (2020), Kalomoiros (2021) and Kalomoiros and Schwarz (2021) for experimental evidence supporting this claim. The sentence in (1a) contains a presupposition trigger stopped, which introduces a presupposition p = ‘she used to smoke’ at the level of the clause she stopped smoking altogether. Being a presupposition, p projects to the level of the whole sentence in (1a) from under and, think and negation in the main clause. It comes into a contradiction with the given context (I don’t know whether Rosa ever smoked or not) and the sentence is predictably judged as infelicitous. The sentence in (1b) is truth-conditionally equivalent to (1a). Moreover, it contains the same presupposition trigger stopped, which introduces the same presupposition, which should project to the level of the whole sentence in (1b) and come into a contradiction with the given context, so (1b) should also be judged infelicitous, but it is not.

Contrasts like the one in (1) have led many researchers to the conclusion that a presupposition does not impose a requirement on the global context of the whole sentence that contains the trigger, but rather on the local context of the trigger. The local context is calculated based on the global context and the syntactic context of the trigger (other material in the sentence). In this talk, I will consider various ways of calculating the syntactic context of the trigger and show that the algorithms that have been proposed in the literature (a lexical one, a linear one and a quantifier-type one) all have unsatisfactory consequences. As a response to these problems, I will propose a syntactic algorithm, which avoids those consequences and leads to an unexpected relation between presupposition projection and the nature of syntactic derivation and the nature of Spell Out / Transfer.

Colloquium 4/7 - Ofelia Zepeda (The University of Arizona)

Speaker: Ofelia Zepeda (The University of Arizona)
Title: The Varied Roles of Native American/Indigenous Linguists
Time: Friday, April 7th, 3:30pm - 5pm


Abstract: In the late 20th Century, a small handful of Native Americans who were speakers of their language were taken under the wing by a few established non-Native linguists with the intent to introduce them to linguistics and train them in the field so that they might become linguists working on their own language or related fields. This presentation will provide a review of the modern and short history of these Native American/Indigenous linguists. The presentation will then elaborate on the newest and upcoming group of Native American/Indigenous linguists and how some of them were called, designate, propelled or chose to go into linguistics primarily due to the dramatic and devastating impact of language endangerment and language loss in their communities. Having worked with some of these students I find that they know that they can find themselves in seemingly insurmountable situations in this field and within their communities. These students persevere understanding that skills in linguistics is one of the important tools in their efforts in language reclamation.


Exp/Comp (3/24) [virtual]: Curtis Chen and Martin Hackl (MIT)

When: Friday, March 24 @ 2pm.
Where: Online. Zoom link TBA. 
Title of Talk: Towards a computational model of reference resolution and MaxP! effects in “Haddock descriptions” 

Syntax Square 3/21 - Juan Cancel (MIT)

Speaker: Juan Cancel (MIT)
Title: The suffix -γi in Central Alaskan Yupik: Antipassive and Applicative Marker, or just an Applicative Marker
Time: Tuesday, March 21st, 1pm - 2pm

Abstract: For my undergrad thesis, I looked at -γi, a valency-changing suffix in Central Alaskan Yupik (CAY) with adversative/malefactive qualities. When the suffix appears in ergative-aligned transitive verbs, -γi is the most productive marker of the antipassive, but when it appears in accusative-aligned transitive verbs, -γi marks the applicative, adding a new argument with absolutive case. In addition to this, when it appears in intransitive verbs, -γi still marks the applicative, but the newly added argument appears with ergative case. Although most of the literature has subsumed -γi as functioning both as an antipassive and an applicative marker, I argued that -γi is just an applicative marker and that its antipassive use is the result of zero -derivation, another valency-changing operation in CAY.

LF Reading Group 3/22 - Tanya Bondarenko (Harvard Universiy)

Speaker: Tanya Bondarenko (Harvard Universiy)
Title: Veridicality mismatches in Javanese
Time: Wednesday, March 22nd, 1pm - 2pm

Abstract: In this talk I discuss a violation of the Spector & Egré’s generalization about the correlation between veridicality in declarative and interrogative embeddings, (1).

(1)Spector & Egre (2015)’s Generalization:
A responsive predicate is veridical with respect to its interrogative complement (like know + question = knowing the true answer to the question) if and only if it is veridical with respect to its declarative complements as well (know + declarative entails —in fact presupposes— that the declarative is true). (Spector & Egre 2015: 1732)

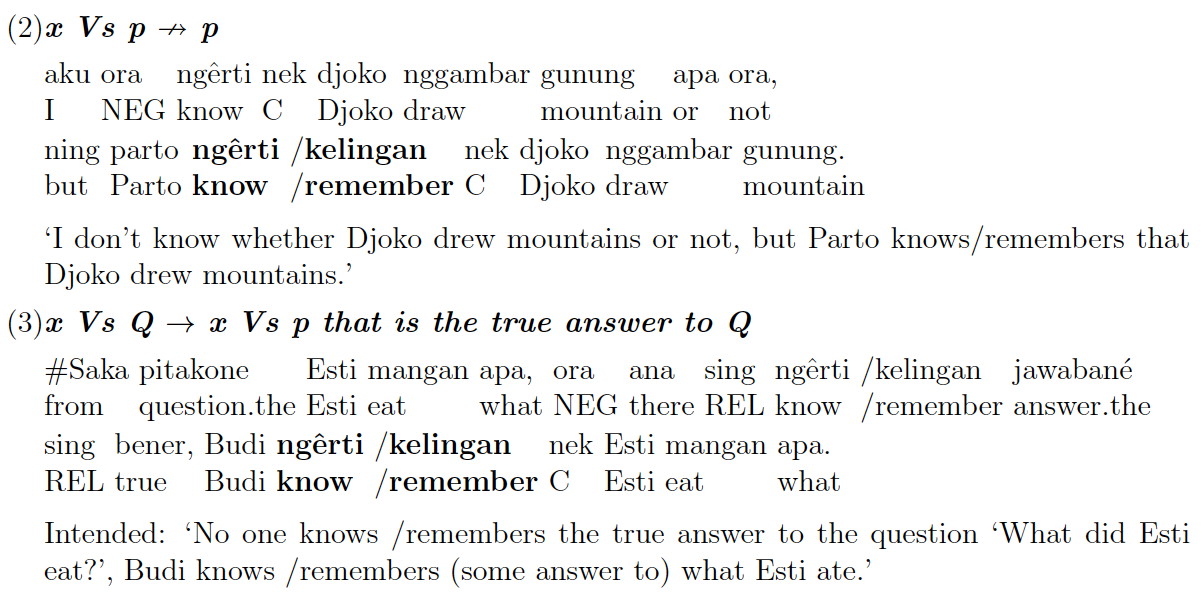
The counterexample to the generalization comes from Javanese: the verbs `know’ (ngêrti) and `remember’ (kelingan) in this language are veridical with respect to question embedding, (3), but, surprisingly, are not veridical with respect to the declarative embedding, (2).

I propose that this pattern emerges from a combination of two factors: (i) embedded clauses in Javanese are always adjuncts, and compose with verbs as modi ers that specify the propositional content of the verbal eventuality (see Bogal-Allbritten 2016, Elliott 2017, Bochnak & Hanink 2021, Bondarenko 2022, a.o.), which leads to the lack of veridicality with declarative embedding; (ii) propositional content associated with ngêrti `know’ and kelingan `remember’ is required to be a single proposition, which in cases of interrogative embedding triggers insertion of an answerhood operator (Dayal 1996) that gives rise to veridicality. I furthermore show that while ngêrti `know’ is non-veridical with declarative complements, it is different from `think/believe’: it comes with a presupposition that the embedded proposition is not known to be false. I suggest to encode this restriction as a definedness condition on the propositional content associated with the mental state that ngêrti denotes.

References
Bogal-Allbritten, Elizabeth. 2016. Building meaning in Navajo. University of Massachusetts Amherst dissertation.
Bochnak, Ryan & Emily Hanink. 2021. Clausal embedding in Washo: Complementation vs. modi cation. Natural Language & Linguistic Theory. 1-44.
Bondarenko, Tatiana. 2022. Anatomy of An Attitude. MIT dissertation.
Dayal, Veneeta. 1996. Locality in WH-quanti cation: Questions and relative clauses in Hindi. Dordrecht: Kluwer Academic Publishers.
Elliott, Patrick. 2017. Elements of clausal embedding. UCL (University College London) dissertation.
Spector, B. and Egr e, P., 2015. A uniform semantics for embedded interrogatives: An answer, not necessarily the answer. Synthese, 192, pp.1729-1784.

MIT Linguists @ MIT Spring Spark

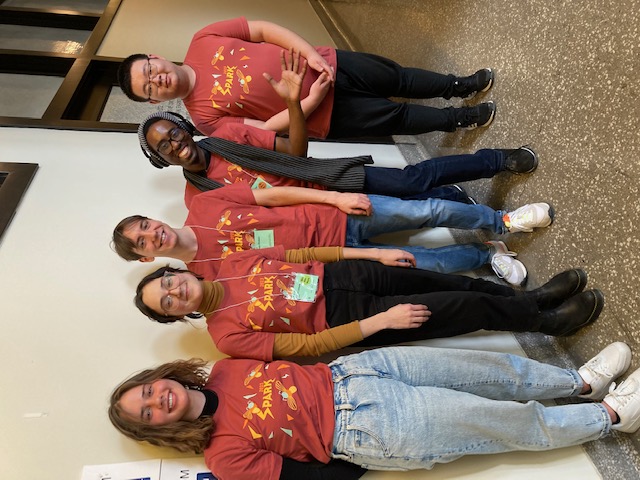
Students in 24.S95 Linguistics in K-12 Education—Aspen Abner, Cora Lesure, Lorenzo Pinton, Christopher Legerme, and Vincent Zu—are all smiles after teaching 7th and 8th graders at MIT’s Spring Spark on Saturday, March 18. Not surprisingly, the course that they designed and taught, Linguistics: The Science of Language, sparked a lot of interest!

LingLunch 3/23 - Ksenia Ershova (MIT)

Speaker: Ksenia Ershova (MIT)
Title: Licensed to license: Deficient probes in West Circassian nominalizations
Time: Thursday, March 23rd, 12:30pm - 2pm

Abstract: This talk argues for a context-dependent, counter-cyclic view of φ-probe feature deficiency: verbal probes must be licensed by the highest head in the extended projection (C^0) in order to agree with and license nominal arguments. This is supported by verbal nominalizations in West Circassian (WC), which, despite being as large as TP and including the full range of verbal φ-probes, cannot expone verbal φ-agreement, assign case or license arguments. The proposal may be extended to other instances of probes being licensed by a higher projection, e.g. ERG-assigning v^0 in Hindi (Legate 2008) or genitive of negation in Russian (Bailyn 2004).

Colloquium 3/24 - Vera Hohaus (Manchester)

Speaker: Vera Hohaus (MIT)
Title: Linguistic Illusions Revisited: The Role of Maximal Informativity
Time: Friday, March 24th, 3:30pm - 5pm

Abstract: Building on joint work with Nadine Bade (Universität Potsdam) and Ryan Walter Smith (The University of Manchester), this talk revisits two prominent cases of linguistic illusions that involve comparison, so-called depth-charge sentences like (1) and under-over illusions like (2).

(1) No head injury is too insignificant to be ignored.

(2) The importance of the rainforest cannot be underestimated.

We demonstrate that both the pedantic and the intended interpretation of these sentences can be derived compositionally. The alleged illusion arises from the interaction of maximal informativity with the monotonicity of the degree predicate underlying the comparison.

MIT @ PLC47

The 47th Penn Linguistics Conference took place at the University of Pennsylvania on over the weekend (March 18-19). The program included presentations by the following members of the MIT community:

  • Adèle Hénot-Mortier (4th year): Superiority effects and the French Plural Pronoun Construction
  • Katya Morgunova and Anastasia Tsilia (2nd year): Why would you D that? On the D-layer in Greek clausal subjects

Creteling 2023!

The 5th Crete Summer School of Linguistics, or ‘CreteLing’, will take place from July 15 to July 28, 2023 at the University of Crete in Rethymno, Greece.

As in other years, a number of current faculty, as well as current and former students will be involved.

Current MIT faculty Adam Albright, Kai von Fintel, Shigeru Miyagawa, David Pesetsky, Norvin Richards, and Donca Steriade will be teaching classes, along with alumni Karlos Arregi, Paul Kiparsky, Ömer Demirok, Pritty Patel-Grosz, Doug Pulleyblank, and Philippe Schlenker. They will be joined by many wonderful colleagues from around the world.

Besides the wide range of courses offered across four parallel sessions, the summer school will feature two workshops: ‘Workshop on Language Acquisition’, organized by Artemis Alexiadou, Maria Teresa Guasti, and Uli Sauerland, and ‘Gender Markedness and Defaults’, organized by Luke Adamson. 

For more information, as well as the application form, please consult the school’s website: https://linguistics.philology.uoc.gr/cssl23/

LF Reading Group 3/15 - Ka-Fai Yip (Yale University)

Speaker: Ka-Fai Yip (Yale University)
Title: A compositional account of “only” doubling
Time: Wednesday, March 15th, 1pm - 2pm

Abstract: Cross-linguistically, exclusive particles ‘only’ may be doubled with a single focus association, posing a problem for the Principle of Compositionality (Dutch: Barbiers 2014; German: Hole 2015; Korean: Lee 2005; Mandarin: Hole 2017, Sun 2021; Vietnamese: Hole 2017, Erlewine 2017; i.a.). The predominant account, operator-particle approach (Quek & Hirsch’s 2017; cf. Branan & Erlewine 2023), explains doubling of adverbial and adfocus particles by treating the latter as semantically vacuous concord markers that establish a syntactic dependency with the former. In this study, I focus on an understudied case of ‘only’ doubling of adverbial particles and sentence-final particles (SFPs) in Cantonese (Law 2004, Lee 2019), which is also attested in Mandarin (Erlewine 2011) and Vietnamese (Hole 2013). While I follow the tenet of the operator-particle approach that one particle is dependent on another one (which is an operator), I pursue a different route in two-dimensional semantics concerning at-issueness and argue that both particles have focus-sensitive contributions, distributed in different meaning dimensions. Specifically, the SFPs relate the focus alternative set quantified by adverbial ‘only’, the genuine exclusive operator, to the discourse by requiring the excluded alternatives to be contextually salient. Informally, the SFPs add a “contrastive” flavor to the exclusive focus. I further demonstrate how the dependency between the two particles may be accounted for by the semantics of the SFPs in terms of distinguishing excluded alternatives from the presupposed proposition, and offer a compositional analysis. I will also address issues raised by scalar readings and how to unify non-scalar and scalar uses in ‘only’ doubling.

Breakstone Speaker Series: Shane Steinert-Threlkeld

This week, Shane Steinert-Threlkeld (University of Washington) will give a colloquium talk and two-part minicourse as the first invited speaker of the Breakstone Speaker Series on Language, Mind, and Computation. This brand new speaker series is an interdisciplinary collaboration between faculty from MIT Linguistics, MIT Brain and Cognitive Sciences, and MIT CSAIL. The funding for the series comes in the form of a donation by Micha Breakstone (PhD, Hebrew University of Jerusalem). 

Abstracts and details about Shane’s visit can be found below. 

Colloquium: Unnatural Language Semantics

When: March 17, 3.30-5pm
Where: 32-141
Abstract: Unnatural language semantics is the study of the meaning of words and expressions in languages that are very unlike natural languages. In this talk, I will present several case studies about how unnatural language semantics can inform us about the structure of natural languages. In particular, I will explain and present several case studies of two methods for explaining semantic universals (shared properties of meaning across the languages of the world).  One method argues that, at the individual word level, such universals arise due to learnability.  The other method suggests that, at the language level, they arise due to optimally trading-off the competing pressures of simplicity and informativeness. The talk will conclude with some discussion about the connections between the two approaches as well as other applications where unnatural language semantics can be helpful.
 
Reception immediately following talk. RSVP here.
 

Mini-course: The Artificial Language Toolkit

When: March 15, 3-5pm; March 16, 12.30-2pm
Where: 32-D461
Abstract: This session will introduce the technique of analyzing semantic typology from the perspective of efficient communication, capturing the idea that natural languages optimally balance competing pressures to be simple and to be informative.  After introducing the general framework, we will look at one application in detail: indefinite pronouns.  In particular, we will walk through reproducing this paper in a new software library that we are developing called the Artificial Language Toolkit, which enables linguists and other researchers to provide typological data in easy-to-produce formats and then conducts various efficient communication analyses more-or-less automatically.
 
Paper on indefinite pronouns: http://doi.org/10.1111/cogs.13142
Artificial Language Toolkit (ALTK; still in active development): https://clmbr.shane.st/altk/

Spring Spark Practice Teaching Session

Date/Time: Wednesday, March 15, 5-6 pm
Location: Room 26-142
 
The students in 24.S95 Linguistics in K-12 Education—Aspen Abner, Christopher Legerme, Cora Lesure, Lorenzo Pinton, and Vincent Zu—have designed a mini-course that they will teach at MIT’s Spring Spark, a weekend of classes for 7th and 8th graders on March 18-19. The class is aptly named Linguistics: The Science of Language (see description below).
 
You are invited to the practice teaching session. Please come, participate, and give your feedback on the class. It’s your chance to be a 7th/8th grader again!
 
————————-
Class Description:
Linguistics: The Science of Language
Did you know that language, like all natural phenomena, can be observed and investigated in a scientific way? What is unique about language is that everyone has their own personal and infinite data set living inside their brain. Learn to examine that data the way a linguist would, and puzzle over things that you may not realize you know about the language that you use every day. Learn how linguistics, the science of language, relates to your world and what you’re interested in. 

Exp/Comp Group 3/10: Hayley Ross (Harvard)

 
Date/Time: Friday 3/10 from 2-3:30pm
Location: 32-D831 and on Zoom
Speaker: Hayley Ross (Harvard)
Title: Adjective-noun compositionality in humans and language models
 
Abstract: A key component of human language is compositionality: the idea that we assemble the meaning of a sentence or phrase in a structured process from the meanings of its parts. When language models encounter a phrase like blue cup or fake gun, do they engage in any compositional process? Do they know that a blue cup is a thing which is blue and which is a cup – but that a fake gun is not a gun? I focus on adjective-noun compositionality, specifically with so-called privative adjectives, to try to get insight into whether neural language models learn about compositionality from their next word prediction objective, or whether they are merely memorising specific phrases. For that matter, do humans treat rare but plausible phrases like counterfeit scarf compositionally, or do they actually also rely on conventionalised meaning to know how to interpret such combinations? What is the relationship between frequency and ease of understanding? In this talk, I’ll present a series of experiments designed to tackle these questions.
 

LingLunch 3/9 - Keny Chatain (Institut Jean Nicod (ENS))

Speaker: Keny Chatain (Institut Jean Nicod (ENS))
Title: Reducing Pronoun Accessibility To Presupposition Satisfaction
Time: Thursday, March 9th, 12:30pm - 2pm

Abstract: A pronoun cannot always co-refer with a given DP: while the cases in (1a-c) are natural, the cases in (1d-e) are not interpretable. The problem of pronoun accessibility is the problem of determining which antecedent-pronoun configuration are licit, which ones give rise to deviance. The cases in (1) point to a simple generalization: the pronoun “it” can co-refer with “a phone-book” if and only if the existence of a phone-book can be taken for granted at the point where the pronoun “it” is used. Simple though it may seem, this generalization is not fully validated by many current theories of pronouns. Such theories typically under-generate, failing to license cases like (1c) as well as other more complicated examples.

(1)
a. There is a phone-book7 and it7 is in the cabinet.
b. If there is a phone-book7, it7 is in the cabinet.
c. Either there isn’t a phone-book7 and it7 is in the cabinet. (attributed to Partee)
d. # Either there is a phone-book7 or it7 is in the cabinet.
e. # There might be a phone-book7 and it7 is in the cabinet.

Taking the generalization at face-value, I propose a system where a pronoun can be interpreted if and only if the existence of a witness - a phone-book in the cases above - can be presupposed. This theory builds on insights from E-type theories (Evans, 1980 ; Heim, 1990 ; Elbourne, 2005) but drops some of the assumptions that have made such theories inviable, like uniqueness.

The benefits are conceptual and empirical. Conceptually, by reducing pronoun accessibility to presupposition satisfaction, the proposal can build upon so-called “explanatory” theories of presuppositions (Schlenker, 2009 ; George, 2008 ; Fox, 2013, a.o.). Such theories derive discourse effects from truth-conditional meaning, instead of baking these effects into meanings themselves (Soames, 1989), as in Dynamic Semantics (Heim, 1983, a. o.). Second, the proposal has a broad empirical coverage: it explains the original cases in (1), but also the more complex quantified cases in (2) of quantifier subordination (Roberts, 1987) and donkey anaphora (Geach, 1962). In addition, it makes a range of new predictions, regarding the possibility of cataphora and pronouns licensed by pragmatic inferences.

(2)
a. Every farmer who has a donkey feeds it hay.
b. Every farmer has a donkey. Few of them feed it hay.

Colloquium 3/10 - Vera Gribanova (Stanford University)

Speaker: Vera Gribanova (Stanford University)
Title: On the sources of case (dis-)connectivity in two types of Russian TP ellipsis
Time: Friday, March 10th, 3:30pm - 5pm

Abstract: Discussions of the identity relation in constituent ellipsis licensing often take for granted, either explicitly or implicitly, the idea that the identity relation in ellipsis ought to be uniform, and applicable across different ellipsis configurations and languages. Recent investigations of this relation — Rudin 2019, Kroll 2019, Anand, Hardt, and McCloskey 2022, Stigliano 2022 — have provided novel evidence and arguments in support of the view that the domain of application of the identity relation is not always coextensive with the domain of the ellipsis itself. For example, although the prevailing view of English sluicing as TP ellipsis historically took the domain of the identity relation to likewise be the TP (Merchant 2001), one of the main findings of the UCSC sluicing dataset is that material above the level of vP — e.g. tense/finiteness, modality, and polarity — can undergo felicitous mismatches. Generalizing beyond English sluicing, this raises the question of whether the domain of ellipsis identity must be a proper subset of the domain of ellipsis itself, or if the specific size of the domain relevant for the identity relation may be variable across languages and ellipsis configurations.

In this talk, I present an investigation of some asymmetries in how case connectivity is enforced in two types of Russian clausal (TP) ellipsis — contrastive polarity ellipsis and fragment answers — and develop an analysis explaining why these asymmetries take the shape that they do. The case study leverages the availability of a well-known case alternation between structural (nominative/accusative) case and genitive case under negation. The first asymmetry is that case connectivity on remnants of these two ellipsis types is enforced fully only in fragment answers, but not in contrastive polarity ellipsis, in which a contrastive DP is fronted to the left periphery, preceding a polar particle (‘yes’ or ‘no’). The second asymmetry is that in contrastive polarity ellipsis, genitive patients under negation in the antecedent can correspond to an accusative patient remnant outside the ellipsis site, but not the reverse. To capture these asymmetries, I develop an analysis of the system of licensing relations that connects the syntax of polarity expression, negative concord, and genitive of negation, and combine this with a formulation of the identity relation in ellipsis in which head-to-head identity between the elided material and the antecedent must be invoked (Saab 2008, 2010, 2022, Tanaka 2011, Rudin 2019, Stigliano 2022).

For the asymmetries between these two types of Russian TP ellipsis to emerge within an internally consistent system of analytical commitments, it is critical that the domain of evaluation for identity be larger than in English sluicing, and likely coextensive with the elided TP. This finding supports a view in which the domain of evaluation for the identity relation in ellipsis may vary across languages and ellipsis types. In the latter part of the talk, I point to a view of ellipsis licensing that can straightforwardly capture such variation, and which arises directly from unifying existing analyses (Aelbrecht 2010, Stigliano 2022) in which certain sub-parts of the ellipsis function — non-pronunciation, syntactic licensing, and the identity relation — can be either grouped together, or broken up across several distinct heads in the clausal spine.

References

Aelbrecht, Lobke. 2010. The syntactic licensing of ellipsis. John Benjamins. Anand, Pranav, Daniel Hardt, and James McCloskey. To appear. The domain of formal matching in sluicing. Linguistic Inquiry. Kroll. Margaret. 2019. Polarity reversals under sluicing. Semantics and Pragmatics 12. Merchant, Jason. 2001. The Syntax of Silence: Sluicing, Islands, and the Theory of Ellipsis. Oxford: Oxford University Press. Ross, John Robert. 1969. Guess who? In Proceedings of the 5th Annual Meeting of the Chicago Linguistic Society. Robert I. Binnick, Alice Davison, Georgia M. Green, and Jerry L. Morgan (eds.), 252–286. Rudin, Deniz. 2019. Head-based syntactic identity in sluicing. Linguistic Inquiry 50 (2): 253–283. Tanaka, Hidekazu. 2011. Syntactic identity and ellipsis. The Linguistic Review 28: 79–110. Saab, Andrés. 2008. Hacia una teoría de la identidad parcial en las elipsis. PhD Dissertation, Universidad de Buenos Aires. Saab, Andrés. 2010. Silent interactions: Spanish TP-ellipsis and the theory of island repair. Probus 22 (1): 73–116. Saab, Andrés. 2022. Grammatical silences from syntax to morphology. A model for the timing of ellipsis. In The Derivational Timing of Ellipsis, ed. Güliz Günes and Anikó Lipták. Oxford: Oxford University Press. 
Stigliano, Laura. 2022. The silence of syntax: A theory of ellipsis licensing and identity. PhD dissertation, University of Chicago.

Bergül Soykan @ Tu+ 8

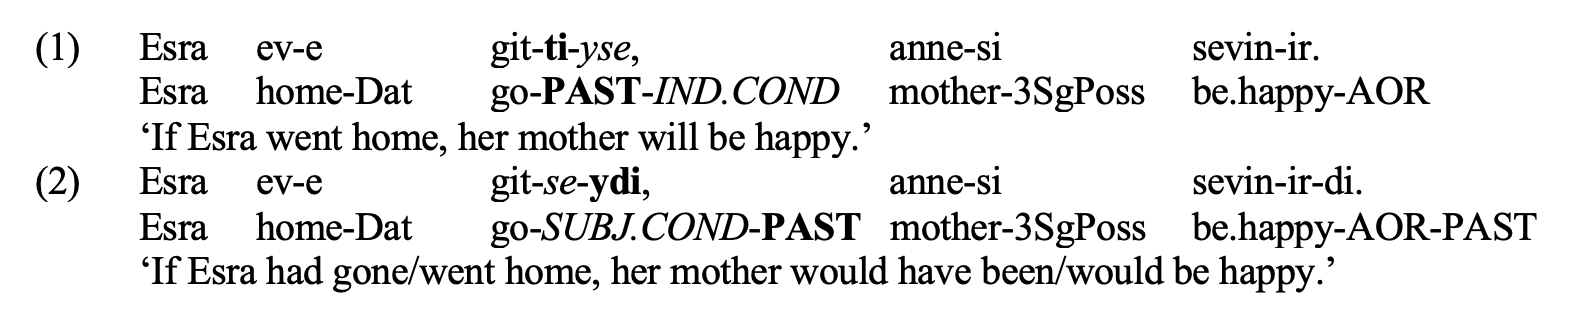
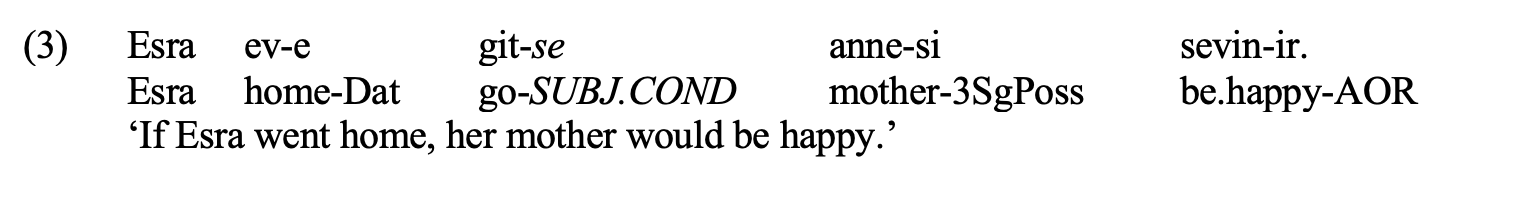
The annual Workshop on Turkic and Langugages in Contact with Turkic (TU+8) was held at Harvard University on March 4-5. Our first-year student Bergül Soykan gave a talk titled “The interaction between past and conditional morphemes in Turkish.” You may find the abstract here. 

The first Inupiaq working group meeting on 3/2

On Thursday, March 2, 1pm, MIT Indigenous Languages Initiative (MITILI) alum Annauk Olin (S.M. 2021) will lead the first Inupiaq working group meeting. On Thursday and at future meetings, the group will aim to piece together grammatical aspects of the Inupiaq language, specific to the Native Village of Shishmaref. All are welcome to join: for more information, please contact Annauk (annauk@mit.edu).  

Phonology Circle 2/27 - Boer Fu (MIT)

Speaker: Boer Fu (MIT)
Title: Mandarin Glide Segmentation: A Language Game Experiment
Time: Monday, February 27th, 5pm - 6:30pm

Abstract: The acquisition of a phonological grammar requires the segmentation of audio input into individual consonants and vowels as a first step. Segmentation is often taken as a given in the study of alphabetical languages, but triggers much debate in Mandarin phonology, especially around the prenuclear glide G in the syllable template CGVX (e.g. [j] in [ɕjɑŋ] ‘fragrance’). Some scholars treat the glide as an independent segment (e.g. Lin 1989). Others claim it is a secondary articulation of the onset (e.g. Duanmu 2007). Still others argue it is nothing more than a natural CV transition (e.g. Ladefoged & Maddieson 1996). These proposals for glide segmentation assume uniform segmentation among Mandarin speakers. I present a language game experiment that shows there is much speaker variation in glide segmentation. The language game is based on Chinese fanqie secret languages (see Chao 1931). In the experiment, Mandarin speakers are asked to swap the onsets of a disyllabic word, in order to encode it as a secret message. For example, [kʰa fej] ‘coffee’ is encoded as [fa kʰej]. What a speaker chooses to do with the glide can inform us of their segmentation of the sound.

Lorenzo Pinton @ S-Babble

On February 21, 2023, our second-year student Lorenzo Pinton gave a talk at S-Babble, a syntax-semantics discussion group at UC San Diego. 


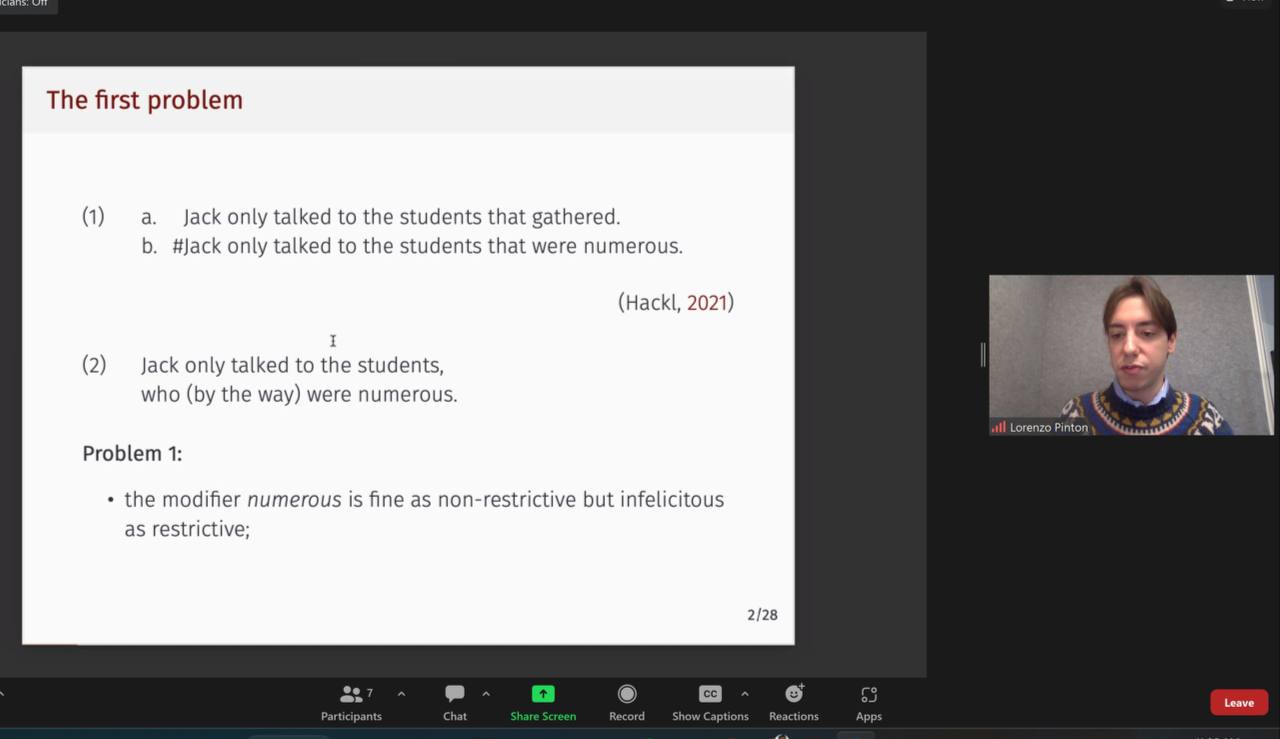
Title: “Numerous” relative clauses: permutation invariance, anti-restrictiveness, triviality

Abstract: It’s been observed that gather-like and numerous-like predicates give rise to different felicity patterns when combined with plural quantifiers (Kroch, 1974; Dowty et al., 1987; Champollion, 2010; Amiraz, 2021):

1)  a.    All the students gathered.

     b.  #All the students are numerous.

In this work, I aim to provide an analysis for similar data brought about by restrictive relative clauses:

2)  a.    Jack only talked to the students that gathered.

     b.  #Jack only talked to the students that were numerous.

While gather can be felicitously applied in a restrictive construction (2a), numerous cannot (2b). First, I will argue, through Italian data, that the problem is really tied to restriction, rather than relative clauses in general. Second, I will claim that predicates like numerous have a specific property, permutation invariance (i.e. the fact that such predicates only care about the cardinality of a group, and not about the specific members that compose that group). This property is problematic when numerous is combined with pluralized predicate, where pluralization is defined as the star operator (Link, 1984). In particular, I will show that when a pluralized predicate modified by numerous combines with the definite article the, it generates triviality, which leads to infelicity (Gajewski, 2002). A positive outcome of this solution is that it  predicts the puzzling data in (3), namely the fact that (2b) becomes good if students is modified by another predicate:

3)  Jack only talked to the gathered students that were numerous.

In fact, we can assume that, when gathered students is not pluralized, it will feed numerous plural individuals (since it is a collective predicate), without leading to triviality. In the presentation I will discuss the conclusion that this solution seems to suggest: namely that pluralization is a rather free operation, which is syntactic in nature and its application is governed by certain logical properties, like avoiding triviality. I would like to conclude showing some problems that might be lurking in the proposed solution, and possible extensions of this solution to the plural quantifiers puzzle in (1) that the literature has focused on so far.


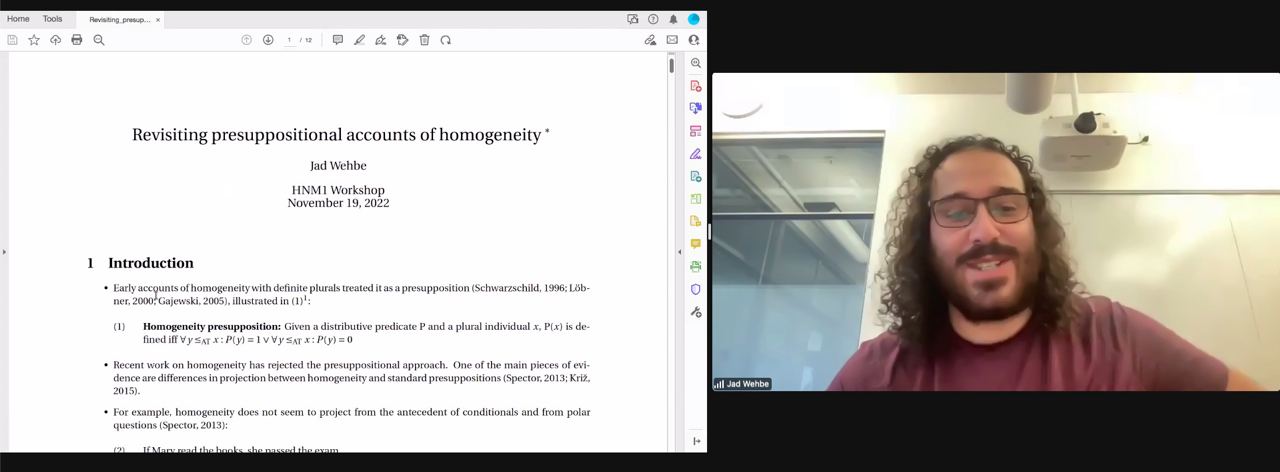
(Thanks to JJ Lim for the screenshot!)

MIT @ ECO-5

Over the weekend, some of us (Bergül Soykan, Katie Martin, Keely New, and Cora Lesure) participated in a very fun and stimulating installment of ECO-5 hosted by the University of Connectiticut in Storrs. ECO-5 is a venue for graduate students from five East Coast universities (UMass, MIT, Harvard, UConn, and UMD) to present their ongoing, original work in linguistics. 

MorPhun 2/23 - Giovanni Roversi (MIT)

Speaker: Giovanni Roversi (MIT)
Title: The morphology of North Sámi adjectives
Time: Thursday, February 23rd, 5pm - 6:30pm

Abstract: North Sámi adjectives are sometimes inflected for case and number, and sometimes not. The pattern is quite complex, and reminiscent of other languages (Hungarian, Turkish, etc.) for which analyses exist on the market, but with added complications that the existing analyses may or may not capture without patches. I want to present some work in progress that tries to take a stab at developing a full account of the North Sámi data, and I’ll highlight the parts that still need some ironing out.

LF Reading Group 2/22 - Amir Anvari (MIT), part 2

Speaker: Amir Anvari (MIT)
Title: Origins of Conservativity
Time: Wednesday, February 22nd, 1pm - 2pm

Abstract: While that natural language determiners denote conservative functions (Keenan & Stavi 1986) is perhaps the most commented on semantic universal, it nevertheless remains unexplained. I will revisit the most promising approach to this puzzle based on the idea that copy theory of movement (Chomsky 1995) makes non-conservative determiners semantically vacuous (Chierchia 1995, Fox 2002,2003, Sportiche 2005). The only serious study of this idea was done by Romoli (2015) with the surprising conclusion that non-conservative determiners may very exist but we cannot be sure as, within copy theory of movement, such determiners are bound to yield the same truth-conditions as conservative ones. First, I will address Romoli’s skepticism by leveraging presupposition projection to argue that all determiners are in fact lexically conservative. Second, I will argue that, with appropriate auxiliary assumptions about the denotation of determiners, Schlenker’s (2009) theory of presupposition projection coupled with Fox’s (2002,2003) rule of trace conversion correctly predicts all determiners to be conservative within the copy-theoretic framework. Third, I will explore a double strengthening of this result by suggesting that (a) conservativity is explained by presupposition projection even without copy theory of movement and (b) the fact that natural language determiners denote generalized (i.e. restricted) quantifiers to begin with is also due to presupposition projection. Finally, I will argue that this work raises the bar on what counts as an acceptable, explanatory theory of presupposition projection by comparing the main result based on Schlenker’s theory of presupposition projection with the predictions made by the Strong Kleene system (Fox 2012).

WAFL 17 in Mongolia!

The Workshop on Altaic Formal Linguistics (WAFL) 17 will be hosted by the National University of Mongolia, Ulaanbaatar, September 27, 28, 29, 2023. This year, our colleague Norvin Richards is among the invited speakers!

Abstracts are invited for 20-minute talks (plus 10-minute discussions) and for posters on topics dealing with formal aspects of any area of theoretical Altaic linguistics, including phonology, morphology, syntax, semantics, or pragmatics. The term ‘Altaic’ is understood to include Turkic, Mongolic, and Tungusic languages, as well as Korean, Japanese, Ryukyuan, and Ainu.

The deadline for abstracts is April 14, 2023.

LF Reading Group 2/15 - Amir Anvari (MIT)

Speaker: Amir Anvari (MIT)
Title: Origins of Conservativity
Time: Wednesday, February 15th, 1pm - 2pm

Abstract: While that natural language determiners denote conservative functions (Keenan & Stavi 1986) is perhaps the most commented on semantic universal, it nevertheless remains unexplained. I will revisit the most promising approach to this puzzle based on the idea that copy theory of movement (Chomsky 1995) makes non-conservative determiners semantically vacuous (Chierchia 1995, Fox 2002,2003, Sportiche 2005). The only serious study of this idea was done by Romoli (2015) with the surprising conclusion that non-conservative determiners may very exist but we cannot be sure as, within copy theory of movement, such determiners are bound to yield the same truth-conditions as conservative ones. First, I will address Romoli’s skepticism by leveraging presupposition projection to argue that all determiners are in fact lexically conservative. Second, I will argue that, with appropriate auxiliary assumptions about the denotation of determiners, Schlenker’s (2009) theory of presupposition projection coupled with Fox’s (2002,2003) rule of trace conversion correctly predicts all determiners to be conservative within the copy-theoretic framework. Third, I will explore a double strengthening of this result by suggesting that (a) conservativity is explained by presupposition projection even without copy theory of movement and (b) the fact that natural language determiners denote generalized (i.e. restricted) quantifiers to begin with is also due to presupposition projection. Finally, I will argue that this work raises the bar on what counts as an acceptable, explanatory theory of presupposition projection by comparing the main result based on Schlenker’s theory of presupposition projection with the predictions made by the Strong Kleene system (Fox 2012).

Welcome to Spring 2023

Welcome to the first edition of Whamit! for Spring 2023! After our winter hiatus, Whamit! is back to regular weekly editions during the semester. 

Whamit! is the MIT Linguistics newsletter, published every Monday (Tuesday if Monday is a holiday). The editorial staff consists of Adam Albright, Kai von Fintel, David Pesetsky, and Keely New. 

To submit items for inclusion in Whamit!, please send an email to whamit@mit.edu by Sunday 6pm.

Passamaquoddy field trip

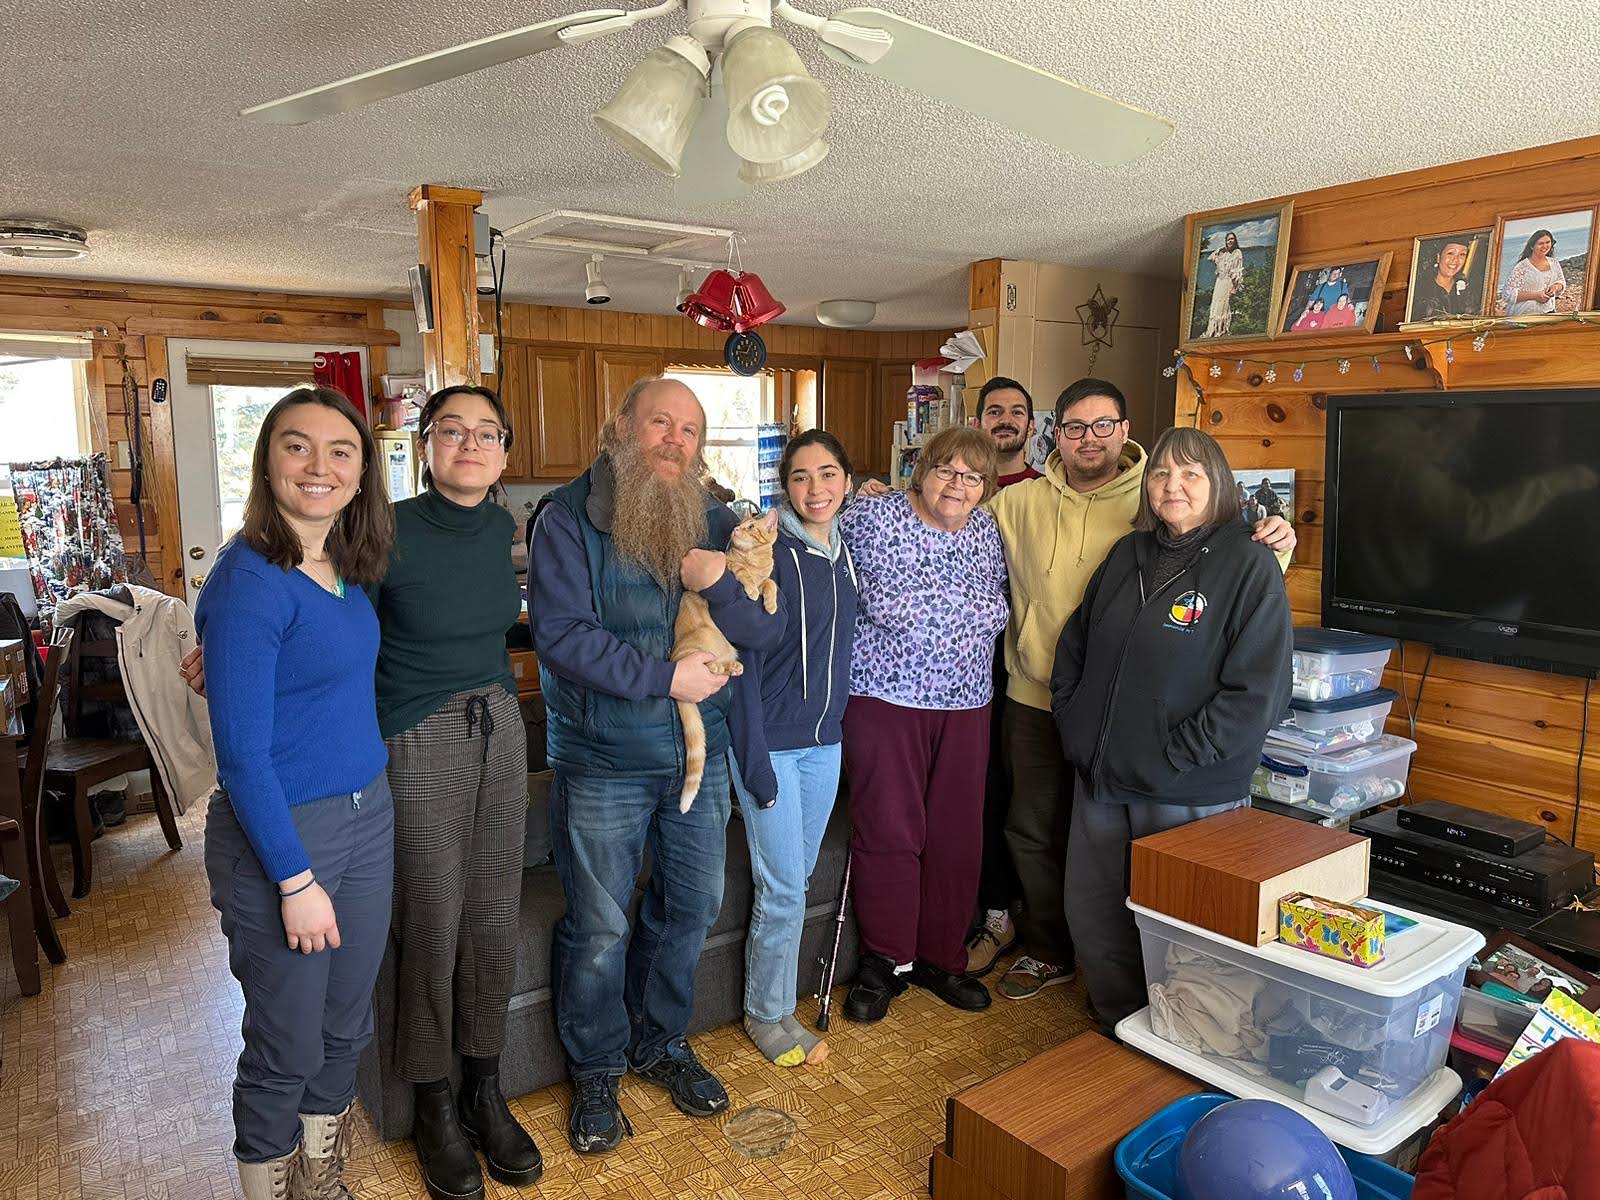
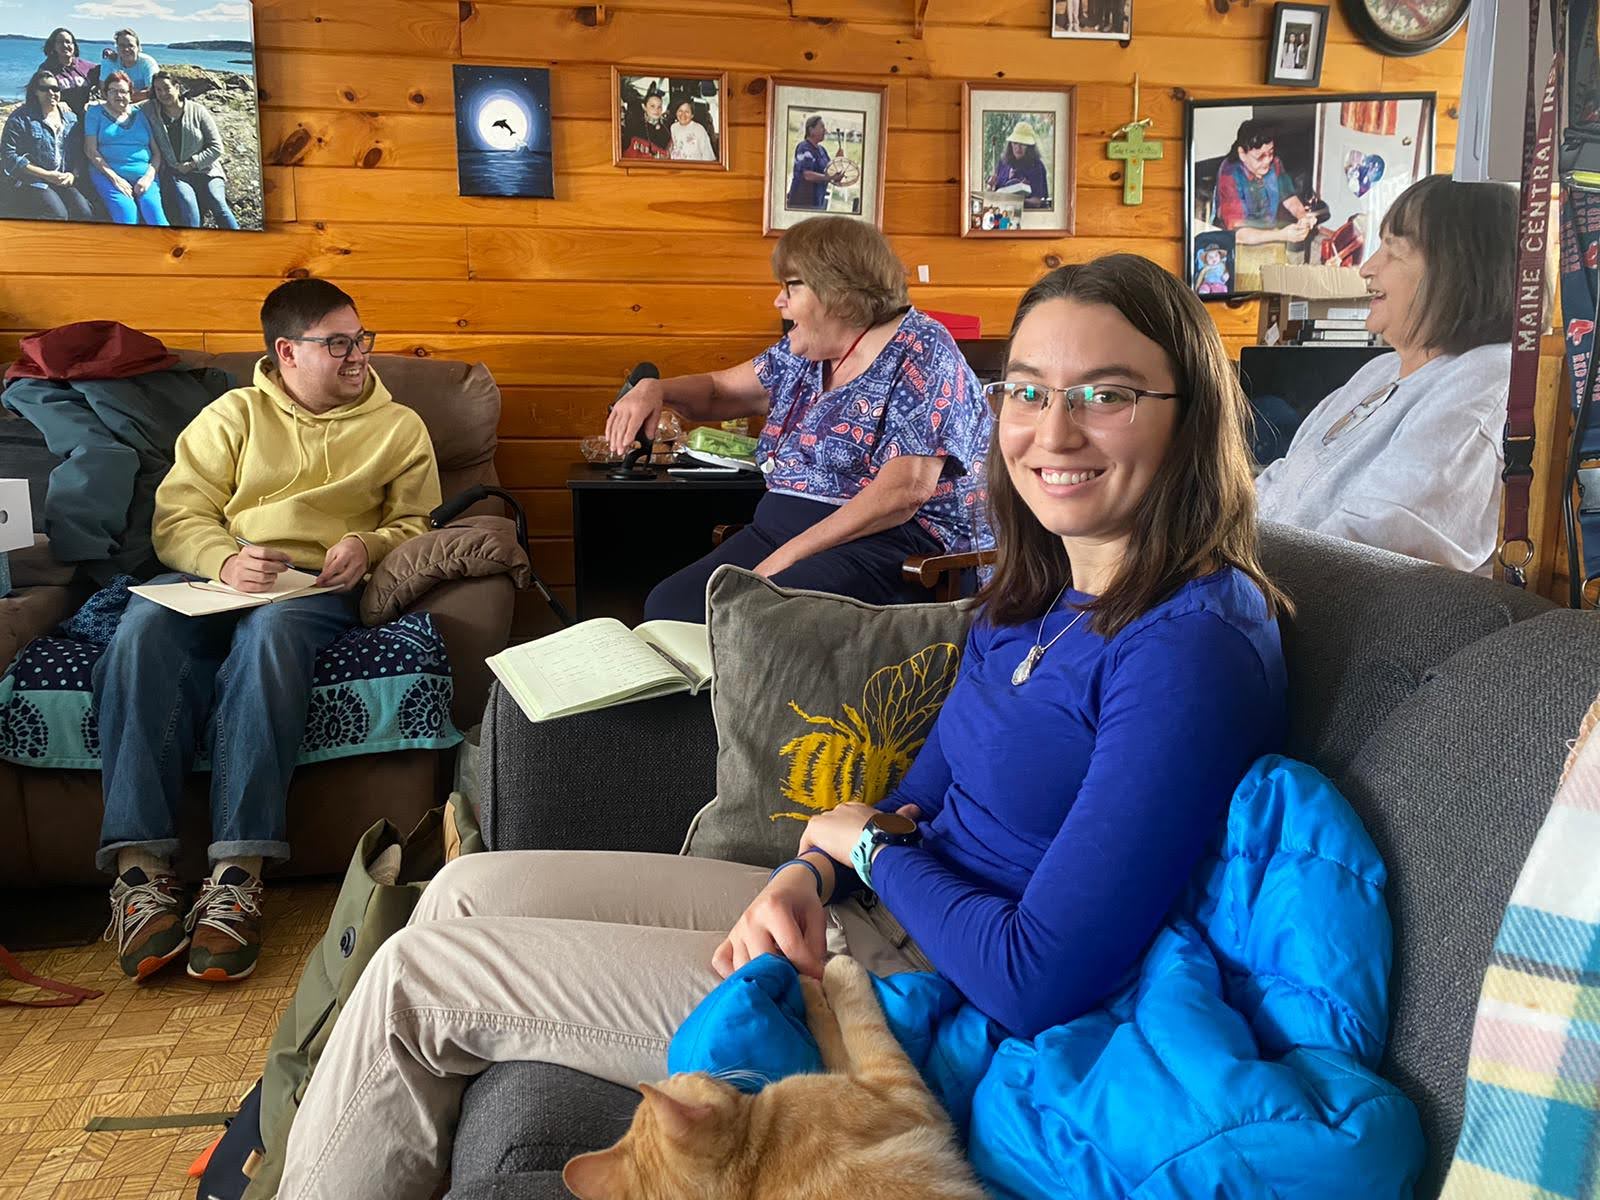
This winter break, a bunch of us MIT linguists (namely, Faith Baca, Peter Grishin, Cora Lesure, Elise Newman, Norvin Richards, and Giovanni Roversi) spent a couple of weeks up in Maine, doing work with Passamaquoddy elders and meeting with language teachers and learners. We learned a lot (about the typology of clausal embedding, the allomorphs of the negative morpheme, conditions on obviative marking into embedded clauses, and the morphological signature of long-distance wh-extraction, among many other things), and we’re eager to go back. If you are a student who’s interested in getting some experience in the field, the Passamaquoddy group is always looking for new members!  You can contact any of us for details, especially Norvin (norvin@mit.edu), or Peter (grishin@mit.edu).


(Photo credits to Elise Newman and Giovanni Roversi)

Extended visit and Minicourse: Juliet Stanton (NYU)

This week, we’re delighted to welcome Juliet Stanton in the deparment for an extended colloquium visit! As part of her visit, Juliet will teach a minicourse over two days.

Speaker: Juliet Stanton (New York University)

Minicourse title: Hiatus resolution in the Cangin languages

Days and times: Tuesday (2/7), 12.30-2pm; Wednesday (2/8), 1-2.30pm

Location: 32-D461

Abstract: The Cangin languages are a small subgroup of Atlantic languages spoken in Senegal. All ban hiatus (sequences of two consecutive vowels) but resolve it in different ways. In two languages, the resolution strategies are not surprising: Palor and Ndut resolve hiatus through a combination of vowel deletion and glide epenthesis. In the others, however, the resolution strategies are more surprising: Noon and Laalaa (and probably Saafi) resolve hiatus through epenthesis of the coronal nasal [n]. Most of the lectures will be devoted to summarizing the patterns, sketching analyses, and determining the degree to which the [n] epenthesis pattern is predicted (or not) by extant theories of consonant epenthesis. This is work in progress, so your thoughts will be welcome!

Colloquium 2/10 - Juliet Stanton (NYU)

Speaker: Juliet Stanton (NYU)
Title: Phonetic rhythm in American English -ization
Time: Friday, February 10th, 3:30pm - 5pm

Abstract: It is commonly assumed that *Clash and *Lapse evaluate syllable-sized constituents: a sequence of two adjacent stressed syllables violates *Clash, while a sequence of two stressless syllables violates *Lapse (see e.g., Prince 1983, Gordon 2002 for *Clash; Nespor & Vogel 1989, Green & Kenstowicz 1995, Gordon 2002 for *Lapse). In this talk I argue, based on patterns of secondary stress in American English -ization, that there exist rhythmic constraints that are evaluated with respect to (normalized) duration. I present evidence consistent with this claim from corpus, judgment, and production studies.

LingLunch 2/9 - Danfeng Wu (University of Oxford)

Speaker: Danfeng Wu (University of Oxford)
Title: Syntax and prosody of coordination
Time: Thursday, February 9th, 12:30pm - 2pm

Abstract: In this talk I present a generalized syntactic analysis of coordination, with a focus on corrective but sentences (e.g., (1a-b)) as the case study. These sentences involve coordination by but, and require presence of negation in the first conjunct and absence of negation in the second (e.g., *Max eats spinach but chard; *Max doesn’t eat spinach but not chard).

(1) a. Max doesn’t eat spinach but chard. b. Max eats not spinach but chard.

Evidence based on scope suggests that negation has two positions in these sentences, though we only hear one. This analysis is consonant with previous proposals for focus-sensitive operators such as the Question-particle and only (e.g. Cable 2007; Hirsch 2017), suggesting that perhaps all focus-sensitive operators have two positions in a sentence. Then I argue using evidence involving constituency, scope and other phenomena that ellipsis can occur to obscure the positions of negation.

In addition to the syntactic-semantic arguments for ellipsis, I present evidence from a prosodic experiment, following a tradition in the literature that draws evidence for syntactic theories from prosodic evidence (e.g. Bresnan 1971; Clemens & Coon 2018). In this experiment, I show that this syntactic analysis makes predictions with measurable effects in prosodic phrasing. The experimental results also suggest that prosodic structure corresponds to syntactic structure more closely than some theories previously claimed.

Course announcements: Spring 2023

Course announcements in this post:

  • Topics in Syntax (24.956)
  • Topics in Semantics (24.979)
  • Topics in Computational Phonology (24.981)
  • Topics in Computational Linguistics (24.982)
  • Special topics: Linguistics in K-12 education (24.S95)

24.956: Topics in Syntax

Subject is one of the most fundamental and most frequently appealed to notions in the discussion of argument asymmetries cross-linguistically. Subjects are taken to display a cluster of properties, which in tree-geometric terms are associated with being the structurally highest argument in the clause. Properties typically associated with subjects include: (i) unmarked (nominative) case; (ii) the ability to control verbal agreement; (iii) the ability to bind anaphors; (iv) the ability to be PRO and to participate in raising; (v) agentivity and thematic prominence; (vi) topicality; (vii) accessibility for wh-movement. In modern Minimalism these properties are distributed across several positions in the clause, but tend to converge on a single nominal due to standard constraints on locality and movement. In this seminar we will explore phenomena that challenge a universally homogeneous notion of subjecthood, focusing on cases where the subject displays only a subset of typical subjecthood properties, or where subjecthood properties are distributed across more than one argument in the clause. We will discuss both the empirical landscape of research on subjecthood and the implications that research has for syntactic theory and our understanding of locality, intervention, licensing, case, agreement, thematic and structural prominence, etc.


24.979: Topics in Semantics 

This semester, we will explore the philosophy of natural language semantics, or meta-semantics. The overarching question will be: what has to be the case for a prominent branch of formal semantics, often referred to as Heim-and-Kratzer semantics, and various specific proposal made within it over years, to make any sense? The course will be split in two parts. In part one, our attention will be focused on what makes formal semantics formal: the emphasis on entailment and contradiction. These concepts seem to play important and diverse roles in semantic theorizing and, by extension, linguistic theory. What does this tell us about language and, by extension, how the mind works? In part two, we will discuss a series of issues, some of which may already be raised in part one. Possible topics include internalism vs externalism; the prospects for referential semantics; the idea of natural language metaphysics/ontology; the position of semantics vis-a-vis cognitive science and/or philosophy; questions of expressive power and type economy; issues of modularity; the connection between language and thought; critiques of mainstream formal semantics from authors like Chomsky, Jackendoff, and Pietroski.

We concur with the following from Bob Stalnaker’s seminar description: “The schedule will be flexible and open ended, following the discussion where it leads, and spending as much time on each topic as it seems to need. That is, we will make it up as we go along.”

As usual, to receive credit, we expect active participation in seminar meetings, weekly emailed questions and comments, and a final paper.


24.981: Topics in Computational Phonology

This year’s installment of 24.981 (Topics in Computational Phonology) will focus on categorical phonology and will address the perennial issue of OT’s strict domination versus HG’s constraint weighting and the additive (or cumulative or gang) effects precluded to the former but allowed by the latter. The tentative plan includes the following issues.

[1] Defining additive effects.
I will put forward a new, purely extensional definition of ‘additive’ effects. We will then discuss it through a couple of concrete examples
that have figured prominently in the literature on additive effects. If the definition makes sense, it affords a way to talk about additive effects (and thus of comparing OT and HG) that makes no reference to constraints, weights, or rankings.

[2] OT and HG as two sides of the same coin. I will introduce the OT and HG implementations of constraint-based
phonology from scratch, trying to formally deduce both of them from the same axiom on additive effects in one fell swoop. This suggests
that, when OT and HG are construed within the huge space of all logically possible implementations of constraint-based phonology, they are quite similar in terms of additive effects: neither of them yields many.

[3] Additive effects in OT and HG.
We will then focus on additive effects in HG and OT, trying to understand which additive effects are indeed within HG’s reach and
which instead require something like ‘constraint conjunction’ in both OT and HG.

[4] OT as ‘margin-free’ HG.
We will then switch to learnability, focusing on ‘online’ or ‘error-driven’ learners (that is, learners that discard each piece of data after having encountered it, rather than storing it). I will review the classical ERCD/GLA theory of online learning in OT. We will then discuss the ideas of ‘margin’ and ‘kernel trick’ in the context of HG. And I will try to conclude that HG, contrary to OT, comes with no good online learners.

[5] Strict domination and exponential update rules.
OT’s strict domination can be mimicked by HG weighting, as long as the weights decay exponentially fast (relative to the size of the constraints). Building on this observation, we will investigate whether learning algorithms with an exponential update rule can be rebooted as OT learning algorithms. We will focus on two cases: ‘AdaBoost’, a batch iterative algorithm; and Winnow, an online algorithm.

Quoting from Amir and Kai’s quote of Bob’s seminar description: “The schedule will be flexible and open ended, following the discussion
where it leads, and spending as much time on each topic as it seems to need. That is, we will make it up as we go along.” As for requirements, I propose the following three: (1) a squib to turn in at the end of the course; (2) four simple problem sets (one every two weeks, during the first two months of the course); (3) taking turns at transcribing classes (that will be taught out of a lean handout, mostly at the blackboard). This course can be used to satisfy the program’s acquisition requirement with a suitable choice of the topic for the final project. Please consult me at the beginning of the semester if you are planning to do so.


24.982: Topics in Computational Linguistics

We will be exploring the relationship between computational models and linguistic theory, with a particular focus on neural models of language (e.g., GPT-3). The main theme of the course will be how neural models should relate to a theory of language. As a means of orienting our initial discussions, we will focus on three papers:

  1. Wilcox, Futrell, and Levy. (2022). Using Computational Models to Test Syntactic Learnability. Linguistic Inquiry.
  2. Baroni. (2022). On the proper role of linguistically-oriented deep net analysis in linguistic theorizing. In Algebraic Structures in Natural Language.
  3. Steinert-Threlkeld and Szymanik (2019). Learnability and semantic universals. Semantics and Pragmatics.

Taking these papers in turn, we will touch on a variety of topics ranging from the relationship (or lack thereof) between grammaticality and probability, acceptability judgments, learnability, and the poverty of the stimulus. Background material will be supplemented as needed and topics expanded depending on interest. Possible additional directions include, probing models for syntactic trees (e.g., Hewitt and Manning, 2019, A Structural Probe for Finding Syntax in Word Representations), superficialism (e.g., Rey,, 2020, Representation of Language), and/or meta-learning for adding linguistic knowledge to models (e.g., McCoy et al., 2020, Universal linguistic inductive biases via meta-learning).

No programming will be necessary for this course. Instead, the goal is to bring linguists from a variety of backgrounds in conversation with recent developments in computational modeling (and the excitement around their ‘abilities’). Supplemental interactive code notebooks may be circulated for those interested in engaging more deeply with the computational experiments highlighted in the course.

For those enrolled there are three requirements, i) active participation in class discussions, ii) posting comments/questions/thoughts on readings via canvas, and iii) a squib to be submitted at the end of the course. Visitors are welcome – either regularly or sporadically! Please send me your email address if you are not registered so that I can add you to the canvas.

Quoting from Giorgio’s quote from Amir and Kai’s quote of Bob’s seminar description: “The schedule will be flexible and open ended, following the discussion where it leads, and spending as much time on each topic as it seems to need. That is, we will make it up as we go along.”


24.S95: Special topics: Linguistics in K-12 education

  • Instructor: Maya Honda
  • Wednesdays, 2-5pm
  • Room: 26-142

In this seminar, we will explore the idea that the study of language in K-12 (kindergarten-grade 12) education can be a means to develop young people’s understanding of scientific inquiry as well as their understanding of the nature of language. We will examine the view that the native language knowledge that each student brings to the classroom comprises a rich, accessible database, which can be used to give students the opportunity to become familiar with the methods, concepts, and attitudes of scientific inquiry. We will probe past and current efforts to engage young learners in linguistic inquiry and consider how to advance this work.

The challenge of this seminar is to create pedagogical materials and methods that will motivate learners of all ages to be inquisitive about their native language and about language in general, with a primary focus on secondary school students (grades 6-12). Seminar participants will work with one another and in partnership with K-12 teachers whenever possible.

There are two prerequisites for the seminar: the first is that you come motivated to making linguistic inquiry accessible to all and the second is that you come committed to collaborating with others in this work. Previous experience teaching linguistics at any level is welcome, but not required. Graduate students from other departments and undergraduates are also welcome if they have taken a linguistics course or if they have the instructor’s approval.

Grishin published in Glossa

We are delighted to announce the publication in Glossa of (dissertating student) Peter Grishin’s paper “Omnivorous third person agreement in Algonquian”.  Congratulations Peter!! Here’s the abstract:

I argue that third person is not underspecified: there must be a distinct third person feature. I add to the existing body of morphological arguments for this conclusion (Nevins 2007; Trommer 2008, a.o.) a syntactic argument: I show that there is omnivorous third person agreement in Algonquian languages. I focus here on two, Blackfoot (Plains Algonquian) and Plains Cree (Central Algonquian), demonstrating that they have an agreement suffix (the peripheral suffix, analyzed as a probe in C) that indexes the number, animacy, and obviation of the structurally-highest third person argument, skipping over first and second person if it has to. I argue that alternative analyses of this agreement pattern in terms of animacy, obviation, and the categorial feature [D] do not work; thus, third person must be specified even in the syntax (contra Preminger 2019).

Glossa is an open-access journal so everyone can access the paper here: https://www.glossa-journal.org/article/id/8874/


MIT @ NELS 53

The 53rd annual meeting of the North East Linguistics Society was held at the University of Göttingen on January 12-14, 2023. Here are the presentations made by current MIT linguists:

  • Ido Benbaji (4th year), Omri Doron (4th year) and Adèle Hénot-Mortier (4th year): Distinguishing levels of morphological derivations in world-embedding models
  • Janek Guerrini (visiting student): Keeping ‘fake’ simple: a similarity-based theory
  • Ido Benbaji (4th year) and David Pesetsky (faculty): E-extension and the Uniformity of Silence
  • Peter Grishin (5th year): How to covertly move: Evidence from Passamaquoddy-Wolastoqey
  • Haoming Li (1st year): The Syntax and Semantics of Asymmetrical ATB Wh-constructions in Mandarin Chinese
  • Zhouyi Sun: Mixed probe, competing for licensing and information-structural neutrality in Shiluk

Other recent alumni who presented their work include:

  • Bronwyn M. Bjorkman (Phd 2011), Elizabeth Cowper, Daniel Currie Hall, Daniel Siddiqi and Isabelle Boyer: Limits on pronominal gender: A semantic account of a morphologicla pattern
  • Carol Rose Little, Scott Anderbois and Jessica Coon (PhD 2010): The iota type-shifter in headless relative clauses: Implications from Mayan 
  • Andrew Nevins (PhD 2005) and Diane Stoianov: Word Order and Differential Object Marking in Three Cohorts of CENA Signers
  • Yağmur Sağ & Ömer Demirok (PhD 2019): Getting even without “even” in Turkish
  • Coppe van Urk (PhD 2015) and Adam Chong: On the preference for nonconcatenative morphology in Dinka
  • Jessica Coon (PhD 2010) and Martina Martinović: Predication, Specification, and Equation in Ch’ol
  • Gaurav Mathur (PhD 2000) and Christian Rathmann: Constraints on interactions between morphological processes and gesture in signed languages 
  • Suzana Fong (PhD 2021): Pronouncing PRO in Wolof
  • Michela Ippolito (PhD 2002): The Hell Bias
  • Aron Hirsch (PhD 2017) and Bernhard Schwarz: Type disambiguation and logical strength 

Privoznov published in Glossa

Congratulations to our postdoctoral associate Dmitry Privoznov (PhD 2021) on the publication in Glossa of his article entitled “Adjunct islands are configurational”! The paper is open access and can be downloaded here. 

This paper argues for the Spell Out theory of the Adjunct Condition, based on Uriagereka (1999), Johnson (2003) and Sheehan (2010), using new evidence from Balkar. The Spell Out theory makes two claims: (a) between any two phrasal sisters at least one must be spelled out and become opaque for movement; and (b) a spelled out constituent does not project its category. This predicts adjuncts to be opaque, since they are maximal projections and are merged with a phrase. The Spell Out theory predicts that modifiers can be transparent for movement, but only if they are merged with a head (as complements) or if their sister is spelled out. The argument from Balkar is based on the behavior of so-called coverbs (clausal modifiers). Balkar converbs come in three varieties: vPs attached at the vP-level or as structural complements, TPs attached between the vP and the T′ of the main clause, and CPs attached at the CP-level. vP-converbs are only transparent for scrambling if they are complements. TP-converbs are never transparent. CP-converbs are only transparent if the main clause that they modify is opaque. Thus, Balkar converbs are transparent in all and only structural configurations that are predicted to be transparent by the Spell Out theory. In the end of the paper I discuss English data from Truswell (2007) and argue that the analysis proposed for Balkar can be extended to them as well.


Zompì and Christopoulos published in NLLT

Congratulations are in order for our dissertating student Stanislao Zompì and co-author Christos Christopoulos (University of Connecticut) whose paper “Taking the nominative (back) out of the accusative” has been published in Natural Language and Linguistic Theory! Félications, Stan and Christos!! The article is open-access and can be downloaded here. 

The nominative, the accusative and the dative have been recently argued to stand in proper containment to one another. In contrast to more traditional decompositions which posited no such containment, this new decomposition has been shown to account for the absence of ABA exponence patterns for this triplet of cases, i.e. for the fact that no rule of exponence applies in both nominative and dative without also applying in the accusative. We point out that, in addition to its desirable predictions regarding *ABA, the more recent decomposition also makes an undesirable prediction about the derivation of ABB patterns, as we show based on data from Indo-European languages. We argue that a third theory—under which the accusative is properly contained within the dative, but the nominative and the accusative do not stand in a containment relation to one another—accounts for all the relevant facts.

MIT @ Amsterdam Colloquium

The 23rd Amsterdam Colloquium took place at the University of Amsterdam on December 19-21. The following MIT grad students presented their work:

  • Ruoan Wang (4th year): Morphological effects on indexical shift in Uyghur
  • Omri Doron (4th year) & Jad Wehbe (3rd year): A constraint on presupposition accommodation
  • Adèle Mortier (4th year), Steven Verheyen, Paul Égré and Benjamin Spector: An experimental investigation of the around/between contrast
  • Lorenzo Pinton (2nd year): Numerous relative clauses: permutation invariance, anti-restrictiveness, triviality
  • Jad Wehbe (3rd year): Revisiting presuppositional accounts of homogeneity

In addition, several recent alumni also gave presentations:

  • Márta Abrusán (PhD 2007): Projection, attention and the meaning of negation (Invited talk)
  • Michela Ippolito (PhD 2002): The Hell with questions 
  • Moshe E. Bar-Lev and Roni Katzir (PhD 2008): Positivity, (anti-)exhaustivity and stability 
  • Yizhen Jiang, Rebecca S. Ren, Yihang Shen, Richard Breheny, Paul Marty (PhD 2017) and Yasutada Sudo (PhD 2012): Plural priming revisited: inverse preference and spillover effects
  • Sonia Ramotowska, Paul Marty (Phd 2017), Jacopo Romoli, Yasutada Sudo (PhD 2012) and Richard Breheny: Diversity with Universality 


Syntax Square (12/13) - Ksenia Ershova (MIT)

Speaker: Ksenia Ershova (MIT)
Title: Manifestations of syntactic ergativity: disassociating high absolutive syntax from the ergative extraction constraint
Time: Tuesday, December 13, 1pm - 2pm
Location: 32-D462

Abstract: Syntactic ergativity is broadly defined as the sensitivity of syntactic rules to the distinction between subjects of transitive verbs (= ergative) on the one hand and objects of transitive verbs and subjects of intransitive verbs (= absolutive) on the other hand. The defining property of syntactically ergative languages is taken to be the ergative extraction constraint: while absolutive arguments are accessible for extraction, A’-movement of the ergative argument is ungrammatical (Deal 2016; Polinsky 2017, a.o.). A prominent analysis of syntactic ergativity involves the movement of the absolutive object to a position above the ergative agent (Aldridge 2004,2008; Coon et al. 2014,2021; Tollan and Clemens 2021, a.o.). In this talk, I argue that high absolutive syntax does not straightforwardly predict the ergative extraction constraint. Despite appearing to be a drawback of this approach, I claim that this is a desirable aspect of the theory. I support this claim with data from West Circassian, a language that displays syntactic ergativity in a range of grammatical domains but does not display a ban on ergative extraction.

Industry workshop (12/7) - Dr. Charlotte Prieu

who: Dr. Charlotte Prieu
when: 12/07, 2pm
where: virtual talk (contact Hadas for zoom link)
what: Charlotte finished her PhD in French Linguistics from the University of Illinois in 2022. In her dissertation titled “Language practices of a digital Black feminist community on French Twitter: gender, race, and sociopolitical discourse”, she worked on gender inclusive language and racial denominations in a social context promoting universalism and colorblindness. She currently works at AWS as a Machine Learning Data Linguist where she annotates linguistic data in English and in French within the Comprehend team.

Minicourse (12/6, 12/8) - Nicole Holliday (Pomona College)

Prosody and Identity in Linguistic Variation: Minicourse

Times: 12/6 and 12/8, 12:30pm-2pm
Location: 32-D461


Variation in intonation and voice quality is among the least well-described phenomena in both phonetic and sociolinguistic research. This is especially a limitation due to research in recent years that has described the importance of such variables for speakers and listeners in presenting and interpreting social-indexical information (Purnell et al 1999, Thomas and Reaser 2004, Holliday 2021). This body of research has also shown that intonation and voice quality variables can carry a range of social meanings that can be controlled and manipulated by speakers both at and below the level of consciousness. Thus, we begin with the premise that speakers’ use of pitch, prosody, and voice quality variables is a robust area to investigate the intersection of language and identity, as well as the nature of phonetic variation. In this minicourse, participants will be introduced to basic concepts in sociophonetics, with special attention to prosodic and voice quality variables. The course will concentrate on the theory and application of methods that help to elucidate how speakers communicate various aspects of personal identity, as well as how listeners perceive them. These fundamental aspects range from the community-level, such as region and race/ethnicity, to the more individual-level, such as persona construction.

On the first day of the minicourse, learners will be introduced to the major questions of sociolinguistics in the 21st century, as well as sociophonetic methods and analytic procedures, with a focus on prosodic and voice quality variables. The readings for this day come from Erik Thomas’ influential textbook, Sociophonetics: An Introduction (2011), in order to provide students will an equitable starting point for better understanding such analyses. On Day 2 of the minicourse, participants will read two journal articles that focus on different types of questions in sociophonetics. The first paper, Thomas and Reaser (2004) is a foundational work that describes several decades worth of research on the issue of ethnic identification in sociolinguistics. The second paper, Burdin, Holliday, and Reed (2022), is a more recent study focusing on describing production-level differences between speakers of three different lects of American English. Participants will leave with a better understanding of how prosody works in sociolinguistic variation, which will enhance their ability to ask questions about variation that they may encounter in their own research.

References:

Burdin, R.S., Holliday, N.R. and Reed, P.E., 2022. “American English pitch accents in variation: Pushing the boundaries of mainstream American English-ToBI conventions”. Journal of Phonetics, 94, p.101-163.

Holliday, N.R., 2021. “Perception in black and white: Effects of intonational variables and filtering conditions on sociolinguistic judgments with implications for ASR”. Frontiers in Artificial Intelligence, pp.102.

Purnell, T., Idsardi, W. Baugh, J. 1999. “Perceptual and Phonetic Experiments on American English Dialect Identification.” Journal of Language and Social Psychology 18 (1): 10–30.

Thomas, E.R. and Reaser, J., 2004. “Delimiting perceptual cues used for the ethnic labeling of African American and European American voices”. Journal of sociolinguistics, 8(1), pp.54-87.

Thomas, E.R. 2011. Sociophonetics: An introduction. Basingstoke and New York: Palgrave Macmillan.

Colloquium (12/9) - Nicole Holliday (Pomona College)

Title: Sociophonetic Variation and Human Interaction with Digital Voice Assistants

Location: 32-141
Time: 3:30pm-5pm, 12/9

Abstract: As technology that relies on speech is increasingly integrated into modern American society, voice assistants are becoming a more significant part of our everyday lives. This talk will present the results of three studies that focus on social perception of voice assistants, voice quality variation among the assistants themselves, and how one assistant’s “tone of voice” evaluation reinforces systematic linguistic bias. Results of the first study demonstrate how listeners engage in racialized judgments of digital voice assistants and that these judgments interact with perceptions of the personality of such assistants, providing evidence that listeners personify these voices. Results of the second study shed light on the voice quality features that may trigger judgments of speaker race and personal characteristics, even when the speaker is non-human. Finally, results of the third study show the ways in which speech recognition technology can reinforce and perpetuate bias against already marginalized groups of speakers. A more comprehensive understanding of how sociolinguistic variation interacts with the design of such assistants may help us to understand how listeners process variation and make judgments of voices, both digital and human. Additionally, a thorough analysis of how computational systems police speaker behavior can help us address systematic inequality as the linguistic line between humans and computers becomes increasingly porous.

LF Reading Group 12/7 - Omri Doron and Jad Wehbe (MIT)

Speaker: Omri Doron and Jad Wehbe (MIT)
Title: Post-Accommodation Informativity
Time: Wednesday, December 7th, 1pm - 2pm

Abstract: We discuss a constraint on global accommodation proposed by Heim stating that an accommodated presupposition must not settle the QUD (Heim, 2015). We argue that this constraint follows from the asymmetry between the pragmatic status of presuppositions and assertions assumed by the satisfaction theory (Stalnaker, 1970; Kartunen, 1974). We provide evidence that local accommodation is sensitive to this constraint, thus arguing that local accommodation maintains the asymmetry. This poses a challenge to theories of local accommodation.

Phonology Circle 12/5 - Aljoša Milenković (Harvard University)

Speaker: Aljoša Milenković (Harvard University)
Title: Markedness is not enough: Tone-stress interaction in Optimality Theory revisited
Time: Monday, December 5th, 5pm - 6:30pm

Abstract: As a general tendency in many languages, higher tone attracts/is attracted by metrical prominence, while lower tone tends towards metrically weak positions (Goldsmith 1987; Hayes 1995; Smith 2002; de Lacy 2002). The existing Optimality-Theoretic accounts use either negative markedness constraints or prosodic licensing to model tone-to-foot mapping. In this talk, I argue that both markedness- and licensing-based approaches fail to capture the full range of cross-linguistic variation. The markedness-based approach (de Lacy 1999, 2002, 2007) faces two empirical problems. First, it predicts a universal dispreference for higher tone in the weak position of a foot. This prediction is at odds with the stress pattern of Neoštokavian (Standard) Serbian, a South Slavic dialect with tone-driven stress, which preferentially constructs disyllabic trochees with a High-toned nonhead (Bethin 1994, 1998; Zsiga & Zec 2013). Second, given that negative markedness constraints penalize Low and Mid tone in stressed syllables, the theory treats stressed contour tones as marked because of the markedness penalty incurred by their Low/Mid-toned components. Consequently, contour tones are expected to be avoided and/or eliminated under stress. This is inconsistent with the fact that many languages restrict contour tones to stressed syllables, and no language restricts contour tones to unstressed syllables (Zhang 2000, 2001). The licensing-based account (Breteler 2017, 2018; Breteler & Kager 2022) readily explains both the preference for High-toned foot nonheads observed in Serbian and the metrical behavior of contour tones. However, unlike negative markedness constraints, the licensing approach has no means to enforce higher tone in foot heads and lower tone in foot nonheads, thus missing a well-documented empirical generalization. As a solution, I pursue a hybrid approach which combines de Lacy (2002)’s *Nonhead-Tone hierarchy with the licensing constraints of Breteler (2018). The midway approach adopted here is shown to improve the typological coverage of both existing approaches.

Industry workshop (11/30) - Dr. Sherry Yong Chen

who: Dr. Sherry Yong Chen
when: 11/30, 2pm
where: virtual talk (contact Hadas for zoom link)
what: Sherry got her PhD in linguistics from MIT, where she worked on semantics/pragmatics and language acquisition. She currently works as a Knowledge Engineer at Amazon - Alexa AI. In her role, she creates ontological designs to expand Alexa’s question-answering abilities, performs data analyses to understand existing gaps, and does program management for her team’s event coverage. Most recently, she worked on Alexa’s QnA coverage for the midterm election.

To learn more about her team: https://www.amazon.jobs/en/locations/sba-california

Sherry came to the US as an international student, and has experience in navigating the job market and the immigration processes.

Colloquium (12/2) - Sandhya Sundaresan (Stony Brook University)

Speaker: Sandhya Sundaresan (Stony Brook University)
Title: Reconciling replicative & non-replicative processes in syntax
Time: Friday December 2, 3:30pm, 32-141

Abstract:

Many grammatical phenomena are replicative in the following sense: the featural information pertaining to some element A in a syntactic domain D is repeated on some other element B which stands in a c-command relation with A in D. For instance, in cases of clausal φ-agreement, the φ-features of a clausal argument (subject and/or object) are replicated on the clausemate verb. The syntactic operation of Agree in Minimalism (Chomsky, 2001) is specifically designed to capture grammatical replicativeness. This follows from the idea, hardwired into Agree, that syntactic relationships are fundamentally asymmetric, involving dependencies between an independent element and a dependent counterpart. The idea is that the defectiveness of a probe for some (potentially unary) set of features α triggers valuation/checking of α, under c-command, by a local goal which is specified for α. The only possible output of such an Agree operation is a representation involving replication of α across the probe & goal. Under a strongly Minimalist worldview, it is further assumed that all syntactic relationships are derived by Agree, understood in the sense above. This yields the following state-of-affairs: 1. All syntactic relationships are derived via Agree, and; 2. The only possible output of Agree is feature-replication across the Agreeing elements. Ergo. All syntactic relationships must be featurally replicative.

In this talk, I will argue that such a scenario strongly undergenerates. Partially and fully non-replicative processes in grammar do exist – a fairly uncontroversial point. Perhaps more controversially, I argue that a (proper) subset of non-replicative phenomena are (narrowly-)syntactic in nature (piggybacking on prior work in Bobaljik, 2008; Preminger, 2014; Levin, 2015; Yuan, To Appear, showing that case- marking (i) feeds φ-agreement; (ii) is syntactic, and (iii) involves case-competition, not case-licensing). Such cases are fatal to the strongly Minimalist world-view described above since they clearly cannot be derived under Agree, as it stands.

To accommodate these problematic cases, I develop a radically revised model of Agree (renamed RELATE to avoid ambiguity) which abandons the idea that syntactic relationships are (asymmetric) dependencies. RELATE is grounded on the notion that syntactic dependencies are restricted by a generalized OCP constraint that two syntactically local objects cannot be featurally indistinguishable at the interfaces (along the lines of Richards, 2010, with significant deviations). The corollary to this is that a syntactic link between two nodes A & B for some feature α must output a representation where A & B remain distinguishable at LF/PF wrt. some relevant feature β, where β ̸= α. I show that the new powerful algorithm also accurately predicts some long-observed replicative vs. non-replicative differences at LF and PF between local and long-distance anaphora crosslinguistically (Faltz, 1977; Jackendoff, 1992; Lidz, 2001; Reuland, 2011) as well as distinctness effects in predicate-nominal and small clause constructions (Longobardi, 1994; den Dikken, 2007). I believe the model may also be fruitfully extended to capture certain cases of switch-reference (e.g. in Washo, Arregi and Hanink, 2021) and cases of so-called “subset control” (Ackema and Neeleman, 2013) including of partial obligatory control.


Minicourse (11/29-30) - Sandhya Sundaresan (Stony Brook University)

Modeling subset-superset relations in shifty variation

Sandhya Sundaresan, Stony Brook University

 
Sandhya Sundaresan will be here at MIT on an extended visit, during which she will teach a minicourse and give a colloquium talk next Friday. The minicourse is now set to happen on Tuesday, Nov 29 and Wednesday Nov 30, 12:30-2pm. The description of the minicourse is attached below. I will let you all know if she tells me there’s any suggested reading for it. 
 

This mini-course will look at shifty variation in two types of shifty phenomena: (i) perspectival anaphora: i.e. constructions where an anaphor targets the mental or spatial perspective of a salient in- dividual that is not a participant of the utterance-context (Nishigauchi, 2014; Sundaresan, 2018b; Char- navel, 2019), and (ii) indexical shift, delineating cases where the reference of an intensionally embedded indexical pronoun is evaluated relative to the parameters of the intensional predicate rather than wrt. the parameters of the utterance-context (Schlenker, 2003; Deal, 2020; Sundaresan, 2018a).

A striking property of shifty variation is that it is not random but implicationally ordered. For in- stance, the intensional environments that license perspectival anaphora are implicationally restricted in the following sense (an observation going back to Culy, 1994, based on an investigation of perspectival anaphora in 32 languages):

(1) INTENSIONAL HIERARCHY FOR PERSPECTIVAL ANAPHORA:
Speech > Thought > Knowledge > Direct perception

IMPLICATION: if an anaphor is licit in the scope of a certain predicate-class, it is necessarily also licit in the scope of all predicate-classes to its left on the hierarchy.

Analogously, the types of perspective-taking are also implicationally ordered (Sells, 1987):

(2) SOURCE (speaker) > SELF (attitude-holder) > PIVOT (spatio-temporal center): 
If a perspectival anaphor in a given language can be bound under a (predicate that provides a) PIVOT, it will also necessarily be licensed under SELF and, in turn, under SOURCE.

The hierarchy in (1) also regulates the availability of indexical shift (Sundaresan, 2012, 2018a; Deal, 2020) crosslinguistically. Variation in which indexicals may shift, both across languages and in a given environment, are also implicationally restricted. As discussed in Deal (2017, 24), there is no language (or individual structure) that shifts ‘you’ to the exclusion of ‘I’ or ‘here’ to the exclusion of ‘you’ (and ‘I’). But the reverse patterns are amply attested.

The shifty hierarchies described so far have all been documented in the literature. We will look at two additional types of implicational dependency which have been significantly less discussed (based on my recent work in Sundaresan, 2021): (a) implicational dependency between perspectival anaphora and indexical shift: I will present evidence showing that the availability of indexical shift in a given environment entails that of perspectival anaphora in that environment, but not vice-versa; (b) subset- superset relation in the internal structures of shifty vs. rigid indexicals crosslinguistically: I will argue (inspired by work on person restrictions in Raynaud, 2020) that shifty indexicals are weak pronouns with a nominal structure that lacks a D layer while rigid indexicals are strong pronouns whose structure subsumes that of shifty indexicals and contains a D layer.

We will look at how these implicational dependencies can be modelled in a selectional, monotonic syntax and explore their consequences for semantics. In so doing, we will also develop a tentative template of attitude shift which can capture these cross-cutting implications, both across the licensing environments and across the shifty elements.

Hungry Wugs (11/30) - Giorgio Magri (MIT)

Hungry Wugs is an undergraduate discussion group aimed to connect linguistics undergraduates and prospective students with the research going on in our department and broadly, in the field of linguistics, in an accessible way. They have an event this week: 
 
Hungry Wugs discussion group
Date/time: Nov 30, Wednesday, 6pm
Location: 32-D461
Although it is aimed to be accessible to undergraduates, the talk is open to everyone.
 
Our presenter this week is Prof. Giorgio Magri.
 
The title of the presentation is:
 

The shifted sigmoids generalization. 

 
A short summary of the talk:
 

This talk will illustrate the gist of current research in linguistics by discussing a recent, beautiful, mysterious empirical observation: the shifted sigmoids generalization (Hayes 2022). It says that, when four linguistic forms are the cross-product of two independent linguistic dimensions, the empirical frequencies of the four forms fall on two shifted sigmoids, as illustrated by the plots at https://linguistics.ucla.edu/people/hayes/GalleryOfWugShapedCurves/index.htm. I will introduce the generalization and present a couple of results that try to explain what it means and why it holds.


Dinner will be provided after the talk. We ask that prospective attendees RSVP (https://forms.gle/KK535oCqRrhb2Bns9) by Sunday Nov 27, to get a headcount for food.
 

LingLunch (12/1) — Norvin Richards (MIT)

Speaker: Norvin Richards (MIT)

Title: Finding Something to Lean On

Date & Time: Thursday 12/1, 12:30—:40PM

Location: 32-D461, https://mit.zoom.us/j/96057548137

Abstract: 

A number of conditions have the effect that certain phrases are required to end with their heads (even in languages in which heads are not generally required to be final).  One such condition is the Head-Final Filter of Williams (1982), which requires APs modifying nouns to end in A:
 
1.  a proud (*of her daughter) woman
2.  a tough (*to solve completely) problem
 
Another condition, applying to languages in which nominal complements and APs both follow the noun, requires AP to immediately follow the noun (Giurgea 2009, Adger 2012, Belk and Neeleman 2017).  Adger (2012) gives the following Scottish Gaelic examples:
 
3.  an dealbh mòr brèagha [de Mhàiri]
  the picture big beautiful [of Mary]
4.  *an dealbh [de Mhàiri] mòr brèagha
 
A third such condition is the FOFC of Holmberg (2000), Biberauer et al (2014), and much other work, which bans a head-final phrase from having a head-initial phrase as its complement.  The complement of the head-final phrase, like the AP in (1-2) and the material preceding AP in (3-4), must end in its head.
 
In this talk I will outline an account of requirements of this kind, using conditions independently developed in Contiguity Theory (Richards 2010, 2016).  One of the goals will be, not only to account for the patterns described above, but to capture the exceptions; the existing literature on the FOFC, for example, has uncovered a number of apparent counterexamples, and the Head-final Filter is quite widespread but has some well-known exceptions (including Greek and Russian).​

Jad Wehbe @ workshop on Homogeneity and Non-Maximality

Our local homogeneity expert Jad Wehbe (MIT) gave a very well-received talk on 11/19 at the online workshop on Homogeneity and Non-Maximality in Plural Predication and Beyond!

His talk was titled Revisiting presuppositional accounts of homogeneity: 

Later in the day, he also served as a panelist on the panel Homogeneity projection and relation to other gappy phenomena: 

Interview with Paul Elbourne

The well-known philosophy blog “3:16” just published a long and really interesting interview with Paul Elbourne of Oxford University — who the interviewer thinks is a philosopher but we really know to be a semantics graduate of MIT Linguistics (PhD 2002) (in other words, ours). Have a look: here.


Colloquium (11/18) - Wataru Uegaki (University of Edinburgh)

Speaker: Wataru Uegaki (University of Edinburgh)
Time: Friday November 18, 3:30pm, 32-141
 
Title: Factivity alternation and the ‘missing’ veridical reading of interrogative complements
 
Abstract: In a number of languages, some clause-embedding predicates exhibit ‘factivity alternation’, i.e., they allow both factive and non-factive interpretations with respect to declarative complements, depending on the choice of the complementation strategy (Lee & Hong 2016, Jeong 2020 on Korean; Özyıldız 2017 on Turkish; Hanink & Bochnak 2017 on Washo; Bondarenko 2020 on Barguzin Buryat). It is furthermore observed in Turkish and Buryat that the same predicates that license factivity alternation nevertheless only allow veridical interpretations of interrogative complements (Bondarenko 2019; Özyıldız 2019). In this talk, I will provide a concrete analysis of a sub-case of the same observation in Japanese. I will argue that non-nominalised declarative complements in Japanese allow a parse as an adjunct while interrogative complements are true arguments of embedding predicates. Together with the assumption that predicates place a presupposition only to its arguments (cf. Bondarenko 2020), we can derive the obligatory veridical interpretation with respect to interrogative complements. I will furthermore discuss implications of the proposal for the cross-linguistic analysis of different types of embedding strategies, as well as for the analysis of the recurring observations in the literature that question-embedding correlates with veridicality (i.e., that question-embedding predicates are typically veridical; Egre 2008; the observation that, although communication predicates readily allow non-veridical interpretation with respect to declarative complements, their interpretation with respect to interrogative complements are—-at least typically—-veridical (Karttunen 1977; Groenendijk & Stokhof 2015; Spector & Egre 2015, a.o.)).
 

LF Reading Group (11/16) - Jad Wehbe (MIT)

We’re excited to welcome Jad this week! The meeting will be in person, back to our original venue, and we’ll set up OWL for people in the department who want to attend virtually.

Zoom link: https://mit.zoom.us/j/94298987190
Speaker: Jad Wehbe (MIT)
Date and time: Wednesday 11/16, 1-2pm
In-person location: 32-D461

Title: Revisiting presuppositional accounts of homogeneity
​
Abstract: Early accounts of homogeneity effects with definite plurals treated homogeneity as a presupposition (Schwarzschild, 1996; Löbner, 2000; Gajewski, 2005), but this characterization has recently been challenged on the basis that homogeneity does not seem to exhibit the standard projection patterns commonly attributed to presuppositions (Spector, 2013; Križ, 2015). The goal of this talk is to argue that homogeneity is in fact a presupposition, despite the apparent differences. In the first part of the talk, I will show that homogeneity is sensitive to a constraint on presupposition accommodation proposed by Heim (2015). Taking this constraint as a diagnostic of presuppositionality, this provides empirical evidence that homogeneity is a presupposition. In the second part of the talk, I will argue that the only difference between homogeneity and standard presuppositions are the conditions under which they can be locally accommodated. I discuss a related view proposed by Fox (2017) and argue that the differences in projection follow from the fact that homogeneity gives rise to non-connected propositions (in the sense of Engeuhard and Chemla (2021), while standard presuppositions are generally connected. ​

Industry workshop (11/16) - Dr Kim Witten

who: Dr Kim Witten
when: 11/16, 2pm
where: virtual talk (contact Hadas for zoom link)
what: Kim has spent over four decades overthinking absolutely everything and has turned this ability into a superpower for analyzing behavior and communication. With over 20 years of design experience, a PhD in Sociolinguistics, and an accredited diploma in Transformational Coaching, she’s devoted her life to studying what makes people tick.

She’s successfully changed careers several times, gaining experience in corporate, agency, and academic environments in both the US and the UK. Her evolving skillset delves deep into coaching, sociolinguistics, research, design, and development. The core motivation for this work is her desire to gather valuable insights about how people connect with each other and experience the world around them. Exploring language has been her primary focus throughout this work, whether that’s through the lens of visual design, observing behaviour in research, or eliciting stories of lived experience.

Kim began her journey into the underpinnings of language and communication at UC Berkeley, earning an undergraduate degree in linguistics in 2006. She achieved her Masters in linguistics at SFSU in 2010, before making the big leap overseas to complete a PhD in sociolinguistics at University of York in 2015. Her thesis focused on enregisterment and identity in an online community of practice.

Kim’s academic background in sociolinguistics has provided both a strong theoretical and practical basis to fulfil her mission — creating a world full of strategic expert thinkers who are making a huge impact in all that they do. Today, Kim supports people from all over the globe to master their mindset, build their resilience and feel more confident, so that they can create the life they really want and reach their high-impact potential.

Find out more about Kim Witten, PhD

Colloquia by Will Oxford (MIT) last week!

Will Oxford gave two colloquia last week! They were at Boston University (11/7) on The accidental inverse, and at Harvard (11/11) on How to be(come) a direct/inverse language (abstract below). 
 
Abstract for How to be(come) a direct/inverse language:
In a “direct/inverse” alignment system, the agreement morphology that indexes a particular nominal is determined by the nominal’s rank on the person hierarchy rather than by its grammatical function, and a special marker indicates whether the highest-ranking nominal is the agent (direct) or patient (inverse). Algonquian languages are often seen as the prototypical example of such a system, but from a diachronic perspective, the Algonquian direct/inverse pattern is not particularly old: internal and external evidence both point to a reconstructed ancestor in which the agreement morphology shows prototypical nominative/accusative alignment. So where did the direct/inverse pattern come from, and how does the underlying syntax of a direct/inverse language differ from that of a nominative/accusative language? In this talk I propose answers to both questions. Diachronically, I propose that the Algonquian direct/inverse system arose when a gap in an innovative paradigm of verb inflection was filled by the analogical extension of an agreement pattern that was previously dedicated to passive forms. Synchronically, I propose that the direct/inverse pattern reflects the interaction of an object-agreement probe on the Voice head and an “omnivorous” probe on the Infl head. This analysis, formalized using Deal’s (2015) interaction-and-satisfaction model of the Agree operation, provides an elegant account of twelve different distributions of inverse marking across the Algonquian family. These proposals allow the Algonquian system to be integrated more closely into standard typological categories and formal analyses rather than standing as a type of its own. Given the prototypical status accorded to Algonquian in typological and theoretical discussions of direct/inverse marking, the fact that the Algonquian system dissolves into simpler and less unusual parts suggests that a degree of skepticism may be in order for putative direct/inverse systems in other language families as well.) 

Norvin Richards and Roger Paul featured on CBC!

Norvin Richards and Roger Paul are featured on CBC on their efforts to revitalize the Wolastoqey (what used to be called Maliseet) language! 

https://www.cbc.ca/news/canada/new-brunswick/norvin-richards-roger-paul-mit-wolastoqey-linguistics-language-new-brunswick-1.6637660​


Industry recruiter meeting (11/11) - Harry Calvert

who: Harry Calvert (Speechmatics)
when: Friday, 11/11, 9am (note unusual time/date)
where: virtual talk (contact Hadas for link), there is no in-person room for this event
what: We will meet with a recruiter from the startup Speechmatics. Speechmatics is interested in establishing a relationship with MIT linguists and has interesting opportunities for internships as well as full-time employment. We will use this opportunity to ask Harry about the role of a recruiter in general, to get a recruiter’s perspective on the hiring process, including tips and common mistakes they see. Here is a short blurb from Harry:

Speechmatics is a deep learning start-up that has developed the most accurate and inclusive Speech-to-Text engine in the World. Recently raising $62mil in series B funding, Speechmatics is on a mission to ‘understand every voice, in every context’.

Harry Calvert is a Global Talent Partner at Speechmatics with over 7 years experience in Recruitment; attracting some of the smartest minds in AI to conduct cutting-edge research, whilst building relationships with external partners/universities.

Industry workshop (11/9) - Dr. Khia Johnson

who: Dr. Khia Johnson
when: Wednesday, 11/9, 2pm
where: virtual talk (contact Hadas for zoom link), or 5-231
what: Khia Johnson has a PhD in linguistics from the university of British Columbia and currently works as a UX Research Scientist on the Reality Labs Research Audio team at Meta. Her research in graduate school focused on corpus and experimental phonetics and psycholinguistics. In her current role, she conducts behavioral and attitudinal human subjects research to evaluate novel audio technology from the perspective of humans.

For more information about her team’s work, see:
https://about.fb.com/news/2020/09/facebook-reality-labs-research-future-of-audio/
https://www.cnet.com/tech/computing/behind-the-doors-of-metas-top-secret-reality-labs/
https://www.khiajohnson.com/

LF Reading Group (11/9) - Anastasia Tsilia (MIT)

Date and time: Wednesday 11/02, 1-2pm
In-person location: 32-D461
Zoom link: https://mit.zoom.us/j/94298987190

Title:  ”Quasi-ECM” constructions in Modern Greek: Evidence for semantic lowering

Abstract:

MG displays certain attitudinal constructions where an attitude verb may take an accusative object (henceforth ACC DP) followed by a subjunctive CP. Kotzoglou and Papangeli (2007) dub this the “quasi-ECM” construction. The basic pattern is the following:

(1)
I Maria theli ton Yani /o Yanis [na tin aghapai].
The.nom Maria.nom want.prs the.acc Yani.acc /the.nom Yani.nom [comp her.acc love.subj].
`Maria wants John to only love her.’

Hadjivassiliou et al. (2000); Kotzoglou and Papangeli (2007); Kotzoglou (2013, 2017) provide considerable evidence that the ACC DP is base-generated in the matrix clause. We provide additional arguments that this is indeed the case, and we argue that these are proleptic constructions as opposed to object control​. Contrary to what is usually assumed in the literature, given the right context, the pro can be in object position too:

(2) Context: Yanis is a political activist and part of an organization run by me. I want to raise awareness about
the organization and I think that getting someone arrested will give us some publicity to this end. 

Thelo ton Yani [na ton silavi i astinomia].
Want.prs the.acc Yani.acc [comp him.acc arrest.subj the.nom police.nom].
`I want the police to arrest Yanis.’

Cross-linguistically, prolepsis marks a de re (e.g. German (Salzmann, 2017), Nez Perce (Deal, 2018)) or a de re and a third reading (e.g. Tiwa (Dawson and Deal, 2019)). We argue that in MG de dicto readings are also possible:

(3) Context: Little Petros is in kindergarten and he and his friends believe that green dogs exist. One day they are talking about green dogs and Petros bets that exactly three of them will show up at his party.

O Petrakis theli akrivos tris prasinus skilus [na erthun sto parti].
The Petros.dim want.prs exactly three.pl green.acc.pl dog.acc.pl [comp come.subj.pl in-the party]. 
`Little Petros wants exactly three green dogs to come to the party.’

This attitude report does not commit the speaker to the existence of green dogs; in Fodor’s terms (Fodor, 1970), the embedded subject is read opaquely. Thus, proleptic constructions are not always interpreted transparently, contrary to what has been assumed up to now. 

We provide an analysis in terms of semantic lowering, as well as argue that prolepsis in Modern Greek still has more restricted truth conditions than its non-proleptic equivalent derived from movement. Namely, there is a requirement that the DP is part of what causes the CP to happen. So, (1) with the ACC is only felicitous if Yanis takes some kind of action to m​ake the CP hold. ​This suggests that prolepsis is not simply a mechanism to exclude de dicto readings, but a way to express some marked meaning in general (which we formalise for Modern Greek). Finally, we hint at an implicational hierarchy of prolepsis, suggesting that if a language has a de dicto reading, then it also has a third and a de re one.

LingLunch (11/10) - Ido Benbaji & David Pesetsky (MIT)

Speaker: Ido Benbaji & David Pesetsky (MIT)
Title: E-Extension and the Uniformity of Silence
Time: Thursday, November 10th, 12:30pm - 1:50pm

Abstract: At the heart of this talk is the conjecture that all syntactic processes that silence an otherwise overt expression do the same thing: apply an E-feature to that expression (Uniformity of Silence):

(1)
Effect of E-feature
The feature E associated with an occurrence of node α silences every element reflexively dominated by α.

With this conjecture as background, we focus here on the silencing of syntactic heads and argue that at least some phenomena traditionally studied under the special rubric of ellipsis involve nothing more than the extension of an E-feature applied for independent reasons to a slightly higher node:

(2)
E-Extension
Optional: If Hº bears E, copy E to the smallest phrasal node containing H and its selected complement.

We propose that the phenomenon known as Sluicing is simply the result of the E-feature applied by an independently motivated rule (optional in some languages) to the complementizer in a “Doubly-Filled Comp” configuration, optionally extended to the minimal C′ by (2).

Furthermore, the family of phenomena usually studied under the rubric of VP-Ellipsis, including English Auxiliary Verb Phrase Ellipsis, are simple the result of the E-feature that silences the trace of verb raising optionally extended to the minimal V′ or AUX′ containing that verb by (2). This dovetails with proposals by Thoms (2010) and Harwood (2014), among others, which also posit verb movement as a necessary precursor to “VP ellipsis” (in somewhat different ways)

Both phenomena crucially target a phrase minimally larger than the silenced head, yielding the phenomenon dubbed Adjunct Exclusion in recent work (including Landau, passim). We argue that “Adjunct Exclusion” is a subcase of a more general phenomenon of non-complement exclusion observed in both of the ellipsis phenomena studied here, with evidence from English and Hebrew.

Wall Street Journal: Linguist Adèle on the linguistics of Adele

When the Wall Street Journal needed a linguist to weigh in on issues concerning the proper pronunciation of the name of the singer Adele, naturally they consulted with our very own Adèle — graduate student Adèle Mortier — who acquitted herself excellently. Perhaps the first time the word “phonologist” has even appeared in the Wall Street Journal, for one thing — though the reference to “uh-dewl” in the article should be taken with a grain of salt (there were supposed to be some phonetic symbols there, and the name does not rhyme with “duel”).  If you have not used up your four free articles for the month, you will be able to read all about it at https://www.wsj.com/articles/wait-how-do-you-say-adeles-name-even-the-expert-is-confused-11667508528

Screenshot of the important part below:


Industry workshop (11/3) — Katharina Pabst

who: Katharina Pabst
when: 2pm
where: virtual talk (contact Hadas for zoom link)
what: My name is Katharina Pabst (she/her). I will graduate with my Ph.D. in Linguistics from the University of Toronto in November 2022. Since February 2022, I have been working as an Educational Developer at York University where I support the campus community in the development, implementation, and evaluation of learning experiences at the faculty and course levels. I also offer guidance for curriculum review and facilitate workshops and certificate courses for instructors with a focus on eLearning, internationalization, and the Scholarship of Teaching and Learning (SoTL).
 
I originally came to North America as an international student, but became a permanent resident of Canada last year, so I have some experience in navigating the job market as an international student.

Colloquium (11/4) - Michelle Yuan (UCSD)

<

div>

Speaker: Michelle Yuan (UCSD)
Title: Morphological conditions on movement chain resolution: Inuktitut noun incorporation revisited
Time: Friday November 4, 3:30pm, 32-141

Abstract:  
Prior research on the Copy Theory of Movement has suggested that the realization of movement chains may be regulated by well-formedness conditions governing complex word formation, such as the Stray Affix Filter (e.g. Landau 2006; Kandybowicz 2007). This talk provides new evidence for this idea, based on an investigation of noun incorporation in Inuktitut (Eastern Canadian Inuit). At the same time, this talk aims to offer new insights into the nature of incorporation in Inuktitut (and Inuit as a whole), informed by its interactions with clausal syntax.
 
Noun incorporation in Inuktitut (and Inuit) is cross-linguistically unusual, in that a small set of verbs is obligatorily incorporating (i.e. affixal), while for most other verbs incorporation is not possible. I provide novel data showing that, in Inuktitut, incorporated nominals are syntactically active, able to participate in case and agreement alternations and undergo phrasal movement, despite surfacing within the verb complex. That these nominals nonetheless invariably surface within the verb complex even when extracted follows straightforwardly from the aforementioned interaction between chain resolution and morphological well-formedness. Moreover, in contrast to most previous characterizations of incorporation (in Inuit and cross-linguistically), I conclude that noun incorporation at least in Inuktitut takes place to satisfy the morphological requirements of the incorporating verb—and not in response to the structural deficiency of the noun.


Exp/Comp Group (11/4) - Huteng Dai (Rutgers)

 
Date/Time: Friday (11/4) from 2-3:30pm
Location: 32-D831 and on Zoom
Speaker: Huteng Dai (Rutgers)
Title: A Neo-Trubetzkoyan approach to phonotactic learning in the presence of exceptions
 
Abstract: Lexicalized exceptions are a major source of noise in phonological acquisition. In a positive-evidence-only setting, it is common to cope with exceptions with indirect negative evidence from distributional information (Clark & Lappin 2010). Most distribution-sensitive models assume a probabilistic grammar that evaluates the grammaticality of words by their predicted likelihood (Hayes & Wilson 2008). However, a probabilistic grammar conflates all words into the same spectrum of probability and grammaticality. As a result, short attested exceptions become more ‘grammatical’ than longer grammatical words with lower probabilities (Daland 2015). This can be problematic because it blurs the boundary between exceptions and grammatical words. In this talk, I spell out a Neo-Trubetzkoyan algorithm that learns a categorical grammar in the presence of exceptions with respect to a restrictive Subregular (Heinz 2010) hypothesis space and iterative Observed/Expected comparison. I argue that this approach is at least as good as, and appears to be superior to the “Probabilistic grammar + Probabilistic inference” approaches in handling exceptions in the case study of Turkish nonlocal vowel phonotactics.
 

LF Reading Group (11/2) - Katie Martin (MIT)

Speaker: Katie Martin (MIT)
Title: A new presuppositional account for slurs
Time: Wednesday, November 2nd, 1pm - 2pm

Abstract: Preexisting analyses of slurs have treated the negative appraisal associated with their meaning as deriving either semantically, via presupposition or conventional implicature (Cepollaro (2015) and Gutzmann (2015), among others), or pragmatically, via Gricean reasoning (Nunberg (2018) and Bolinger (2017) among others). I respond in this project to two recent works that have criticized these analyses of slurs, both semantic (Lo Guercio 2021) and pragmatic (Falbo 2021).

Falbo (2021) observes that accounts that deem slurs to be semantically equivalent to their neutral counterparts are significantly challenged by what she calls “non-target” uses, such as the following:
(1) Deandra’s a lesbian, but she’s not a dy*e.
(2) Not only is my neighbour a lesbian, but she’s a total dy*e too. She drives a motorcycle and is covered in tattoos.

Under the claim that slurs and their neutral counterparts have identical semantics, (1) should be incoherent and (2) should be redundant – however, this is obviously not the case. Indeed, this data provides a challenge not just for pragmatic accounts, but for semantic accounts as well – if the only difference in meaning between “lesbian” and “dyke” is that the latter presupposes a negative attitude towards lesbians on the part of the speaker, it seems distinctly odd that a single speaker would utter both of the clauses in each of (1) and (2) – and yet such utterances are perfectly natural.

In a similar vein, Lo Guercio (2021) criticizes presuppositional accounts of slurs on the grounds that even bigoted speakers can use “neutral” forms in place of slurs, which ought to cause a violation of Maximize Presupposition, but seems in fact to be perfectly felicitous.

I address these important objections by proposing a theory of slurs in which the presuppositional content associated with the use of a slur is not simply a negative attitude on the speaker’s part towards the group identified by the slur, but rather a negative attitude towards the stereotypes associated with that particular group and, crucially, that these stereotypes are relevant/salient in the conversational context.
(see also abstract attached)

LingLunch (11/3) - Brian Leahy (Harvard)

Speaker: Brian Leahy (Harvard)
Title: Problems with Possibilities
Time: Thursday, November 3rd, 12:30pm - 1:50pm

Abstract: I will present the results of several studies that test preschoolers’ ability to talk about and think about mutually incompatible possibilities. These studies reveal systematic errors in how preschoolers (a) answer questions about what can and has to happen, and (b) form contingency plans when choosing actions in the face of multiple open possibilities. For example, when choosing between a container that must contain a prize and two additional containers that merely might contain a prize, older 2-year-olds choose a risky option half of the time. They take a risk when they could have a sure thing. This error slowly becomes less frequent with age, but is still common among 4-year-olds.

In this talk I will quickly sketch some of the behavioral results, and put an explanation on the table that accounts for the observed patterns of errors: when faced with multiple incompatible possibilities, children use simulation to generate one possible outcome and then treat that outcome as the fact of the matter. They do not mark the simulated outcome as merely possible and check whether there are other possibilities that need to be accounted for.

After sketching the behavioral results, I will present our language comprehension studies. There is no doubt that learning the English modal auxiliary system is difficult: each modal auxiliary can express many different meanings, and many different auxiliaries can express the same meaning. I will present evidence that comprehension of modal vocabulary appears late, around the same time that children start succeeding on the behavioral tasks described earlier. I will argue that the complexity of the mapping problem cannot fully account for children’s struggles. In particular, I will show that there are correlations in children’s ability to answer questions about what has to happen and their ability to apply nonmodal vocabulary like ‘all’ and ‘only’ in the modal domain. Children comprehend ‘all’ and ‘only’ by age 4, so these correlations are surprising if children’s struggles with modal auxiliaries arise only from the complexity of the mapping problem.

What is the additional problem that children face? Why is there such consistency across age in children’s ability to talk about and think about mutually incompatible possibilities? One candidate answer is that the ability to mark representations as merely possible emerges late in the preschool years, typically after age 4. Existing data do not rule out this hypothesis, and it offers a tidy explanation for all of the observed data. This motivates a direction for future research: If the ability to mark representations as merely possible is one that emerges with age, what are the mechanisms by which it emerges?

Industry workshop (10/26) - Sarah Clark

Who: Sarah Clark
when: 2pm
where: virtual talk (contact Hadas for zoom link)
what: I completed my masters in linguistics in 2019 at the University of Illinois at Urbana-Champaign. At the moment, I am working toward my doctorate in linguistics at UIUC. I specialize in sociolinguistics, specifically critical discourse analysis, the interplay of ideology and identity, organizational communication, and military and veteran identity. I have been working during my whole program for the US Army Corps of Engineers’ Construction Engineering Research Laboratory. My duty title is Strategic Communications Officer and I lead all internal organizational communication to support and grow our multi-million dollar portfolio. In other words, I help engineers talk to each other and non-engineers in order to do the mission. Working outside of academia is by far the gold standard for linguists in my opinion - we are linguists who are creative, resilient and have the honor of bringing the power of linguistics to the real world!


LF Reading Group (10/26) - Bergül Soykan

LFRG is excited to welcome Bergül this week! The meeting will be in person, but we’ll set up OWL for people in the department who want to attend virtually.
 
Zoom link: https://mit.zoom.us/j/94298987190
Speaker: Bergül Soykan (MIT)
Date and time: Wednesday 10/26, 1-2pm
In-person location: 32-D461 
 
Title: Past in Turkish Conditionals

Background: The past morpheme in Turkish conditionals can either precede the indicative conditional marker or follow the subjunctive one as shown by (1) and (2), respectively. While (1) can be uttered in a context where the speaker is oblivious about whether Esra went home or not, (2) is most likely to be uttered when the speaker knows that she did not go home, i.e., in counterfactual scenarios.

There are also the non-past subjunctive conditional constructions in Turkish as in (3), which can be licensed in cases where the speaker believes the antecedent event to be unlikely to occur.

Problem: The differences between these constructions can be handled from two perspectives.

PAST [INDICATIVE vs SUBJUNCTIVE]: The antecedent past marker in (1) does not affect the time of its consequent whereas the one in (2) requires the use of past in the consequent clause. Interestingly though, it is not necessary to have the past morpheme in the antecedent to have a past subjunctive conditional; having it in the consequent would suffice without any significant meaning difference. Moreover, while the past indicative conditional only licenses past time adverbials in its antecedent, the subjunctive one can be used with both past and non-past adverbials.

[NON-PAST vs PAST] subjunctive: Although both (2) and (3) are accessible in counterfactual contexts where Esra is not going home at the utterance time, they differ in their presuppositions. For instance, the existence presupposition must hold for the non-past subjunctive but not for the past version; namely, (2) is still available in a context time where Esra is not alive while (3) is not.

Proposal: Considering all these aspects, I claim that the past in subjunctive conditionals is interpreted outside the modal operator (Ippolito, 2002), setting the modal time (“reference time” in her proposal) to the past while the one in indicatives is interpreted inside its own proposition. I suggest that this shift in the modal time of the conditional clause lets us make claims about the future possibilities from a past perspective and hence makes it possible to use non-past time adverbials along with the past ones. However, contrary to Ippolito’s (2002) claim, I argue that past subjunctives hold no presuppositions with respect to the utterance time (Leahy, 2011), to explain the difference between past and non-past subjunctives. In my account, non-past subjunctives have a special speaker-oriented likelihood presupposition, where the speaker considers the antecedent to be more likely to be false than true, in addition to other presuppositions. Nevertheless, the past subjunctive holds no presuppositions and generates the counterfactuality implicature by competing with its past indicative counterpart (Leahy, 2017).


MIT @ AMP 2022 (10/21-3)!

MIT folks presented at the 2022 Annual Meeting on Phonology (AMP 2022) which happened on October 21-23 at UCLA. Donca gave an invited plenary talk, and students and faculty members gave presentations: 

Current students and faculty:

Donca Steriade (Faculty): Vowel-to-Vowel intervals in quantitative meter (Plenary Talk)

Boer Fu (6th year): The Segment Status of the Mandarin Glide: A Language Game Experiment (poster)

Eunsun Jou (4th year): An economy-based amendment to Robust Interpretive Parsing with the GLA (poster)

Giorgio Magri (Visiting Associate Professor, PhD 2009) and Arto Anttila: Paradoxes of MaxEnt markedness (poster)

Canaan Breiss (Postdoctoral Associate, MIT BCS): Lexical Conservatism as an empirical challenge to obligatory cyclic inheritance (talk)

Alums: 


Ora Matushansky (PhD 2002): Russian transitive softening as ablaut

Bingzi Yu and Youngah Do (PhD 2013): The transmission of vowel (dis)harmony: An iterative learning study

Coppe Van Urk (PhD 2015) and Adam Chong: The roots of non-concatenative morphology in Western Nilotic

MIT @ the 54th Algonquian Conference (10/20-23)

Some of MIT presented at the 54th Algonquian Conference this weekend (Oct 20-23) at CU Boulder! 

Peter Grishin (5th year): Subordinative long distance agreement in Passamaquoddy-Wolastoqey and the syntax of the inverse


Peter Grishin (5th year) and Will Oxford (visiting associate professor): Patterns of portmanteau robustness across Algonquian

Happy birthdays to Anastasia Tsilia and Christopher Legerme!

Three of our grad students, Anastasia Tsilia (now 24), Christopher Legerme (now 30), and Shrayana Haldar (now 23) had birthday celebrations in the department last week, complete with cake! Happy belated!

New paper by Aravind & Koring in Language Acquisition

A new paper on the acquisition of syntax has appeared in the journal Language Acquisition coauthored by our colleague Athulya Aravind and Loes Koring (who was a postdoctoral associate and teacher/advisor in our department in 2016-2018) — entitled “Experiencer troubles: A reappraisal of the predicate-based asymmetry in child passives”. Congratulations, Athulya and Loes!
 
You can read the open-access paper (and the abstract) at https://www.tandfonline.com/…/10…/10489223.2022.2115373
 
And for good measure, visit the homepage of the MIT Language Acquisition Lab: https://www.childlanguage.mit.edu.


Giovanni Roversi @ NYU!

Giovanni Roversi presented at NYU’s Ling-Lunch on Oct 13, 2022! 

Title: Where can probes be? Evidence from asymmetric adjectival concord

Abstract: We currently don’t have a theory telling us what kind of probes should or shouldn’t be where; I’m not going to propose one either. In this talk I will make an indirect argument for not wanting too restrictive a theory: the empirical landscape, when looked at carefully, is too varied for us to be able to afford a restrictive theory of probe distribution. The domain I will concentrate on is asymmetric adjectival concord, that is, languages where the morphological patterns on attributive adjectives and predicative ones (“the red car” vs “the car is red”) are different. Concretely, I will look at German, North Sámi and Northern Norwegian, which I argue exhaust the logically possible space of variation for the matter in question (that is: (i) only concord on attributive but not on predicative; (ii) the opposite of that; (iii) concord on both but of different kind). I will try to convince you that especially the North Sámi and Northern Norwegian patterns are real, and will exclude alternative analyses. In other words: the typology of attested patterns does in fact cover all logically possible asymmetries, and our theory should therefore be able to derive all of them.

DeGraff in the NY Times

On October 14, a guest essay by our very own Michel DeGraff appeared in the New York Times: “As a Child in Haiti, I Was Taught to Despise My Language and Myself”. The essay details in a personal and powerful way the effects of language policy on Haitian education and identity, and advocates for the types of change that are promoted by the MIT-Haiti Initiative. Congratulations, Michel!

Beginning of term party @ Mex!

On August 12, 2022, we had a beginning of term party @ Mex, seeing old and new faces with smiles all around! 


MIT News on DeGraff becoming an LSA fellow

MIT News has a nice article about our colleague Michel DeGraff’s having been elected a Fellow of the LSA, as previously reported by WHAMIT!.

Industry workshop (10/19) - Alaina Talboy

 
who: Dr. Alaina Talboy
when: 2:45pm (notice unusual time)
where: virtual talk (contact Hadas for zoom link)
what: Dr. Alaina Talboy earned her PhD Cognition, Neuroscience, and Social Psychology from the University of South Florida. Her research focused on the cognitive underpinnings of data-informed decision making. In 2019, she joined Microsoft where she currently applies her expertise toward improving data governance solutions and industry research ethics. Dr. Talboy’s work is published regularly in a variety of outlets from popular press to high impact peer-reviewed journals. Her book “What I Wish I Knew: A Field Guide for Thriving in Graduate Studies” was released in March 2022.
 
All are welcome; current students might find this speaker particularly helpful.

Phonology Circle 10/17 - Donca Steriade (MIT)

Speaker: Donca Steriade (MIT)
Title: Vowel-to-Vowel intervals in quantitative meter
Time: Monday, October 17th, 5pm - 6:30pm
Location: 32-D831

Abstract: 

I present evidence for V-to-V intervals as units of rhythm, drawn from laws that govern the distribution of word-final V̆C0# sequences in the quantitative meters of the classical languages.

Weight-changes in phrasal contexts: The talk analyzes changes in the weight of word-final V̆(C)# positions between phrase-final and phrase-medial contexts, as diagnosed by the quantitative meters of Greek and Latin. The relevant generalizations are outlined in (2). The top row shows the metrical weight of the first position in a V̆CC0V string containing a word boundary, as observed in dactylic hexameter lines. The 3rd and 4th rows indicate that some phrase medial cross-boundary V̆CC0V sequences are underattested, thus arguably disfavored.       

(2) First position is metrically high First position is metrically heavy
  (a) V̆C#V  (b) V̆#CV (c) V̆#CCV  (d) V̆C#CV (e)  V̆CC#V
Greek   restricted restricted restricted  
Latin   restricted impossible restricted  

The restricted shaded cells contain sequences that are underattested at major junctures in the dactylic hexameter, or absent in all positions. Unshaded cells correspond to favored sequences (V̆C#V is favored over V̆#CV at a major juncture) or unrestricted ones (V̆CC#V compared to V̆CC#CV). Unlike V̆C# and V̆# finals, heavier V̄C0 # and V̆CC(C)# finals are not restricted.

Interval-based and syllable-based analyses: The sequences in (2) are parsed into intervals in table (3), and into syllables in table (4). Shaded cells correspond, as in (2), to restricted sequences:

(3) (a) |V̆C|#V (b) |V̆#C|V (c) |V̆#CC|V   (d) |V̆C#C|V  (e) |V̆CC|#V
(4) (a) V̆.C#V  (b) V̆.#CV  (c) V̆#C.CV  (d) V̆C.#CV  (e) V̆C.C#V

The interval parses in (3) reveal a simple reason for selective underattestation: in all shaded cells, the weight of the word-final interval has changed in the shaded cells relative to its weight in isolation, as one or more Cs were added to it by the following word. By contrast, the word-final interval in (a) and (e) maintains line-internally the same weight as in isolation.

On an interval analysis, all patterns of underattestation outlined in (2-4) emerge as driven by the preference for weight correspondence between intervals in isolation and their correspondents in line-medial or phrase-medial contexts. All substantial changes of weight between the isolation context and the line-medial context are disfavored, and cause poets to avoid the sequence.

Compare now the syllable-based parses, (4). No syllabic factor distinguishes restricted sequences from unrestricted ones. The weight of the first syllable in (4.a) and (4.c) must be attributed, on any syllable-based theory of weight, to the reassignment of a C from one syllable to a neighboring one, turning heavy final V̆C.# into the initial light V̆.C#V in (4.a); and light V̆.# into heavy V̆#C. in V̆#C.CV, (4.e). So both (4.a) and (4.c) have undergone resyllabification, but only (4.c) is restricted. Also hard to explain is why, of the two sequences that begin with a light syllable, VC#V (4.a) and V#CV (4.b), the unrestricted sequence V.C#V is the result of resyllabification. Similarly mysterious is why (4.d) V̆C.#CV, with syllable and word boundaries properly aligned, is restricted, while syllabically misaligned (4.e) V̆C.C#V occurs freely.

LingLunch 10/20: Paul Rössler (Universität Regensburg)

Speaker: Paul Rössler (Universität Regensburg)

Time: Thursday 10/20, 12:30-1:50pm

Zoom link: https://mit.zoom.us/j/98155777682

In-person location: 32-D461

Title: Comma and prefield. What does German orthography tell us about the relation between norm, system and language use?

Abstract:

In text types with distinct nominal style, such as academic texts, the writer tends to mark the extensive complex nominal phrases in front of the finite verb graphically by comma placement. Meanwhile, this phenomenon seems to have outreached the domain of academic texts. The talk reveals how widely this writing practice which is incompatible with the norms of standard German orthography has already spread. This raises the question how linguists and codifiers deal with that pervasive phenomenon of language standardization as players in the field of social forces, and which consequences this entails for teachers as norm authorities and norm mediators.


Professor Rössler is co-PI with Kai von Fintel on an MISTI seed grant on “Comparative Punctuation” and visiting MIT for a couple of weeks.

LF Reading Group 10/19 — Ido Benbaji and Omri Doron (MIT)

Speakers: Ido Benbaji and Omri Doron (MIT)
Title: Adversative only is only only
Time: Wednesday 10/19, 1-2pm
Location: 32-D461

Abstract: 

Jespersen (1954) discusses uses of the word only in which it seems to behave as a sentential connective, as in (1) below. Following von Fintel & Iatridou, we call this adversative only.
(1) He’s a nice man, only he talks too much.
We propose a unified analysis for regular only and adversative only, and suggest that the difference between the uses stems from scopal interaction with an operator in LF that enforces the informativity requirement on sentences. We extend our analysis to other cases of CP-taking only and even.


Upcoming article in NLLT - Ruoan Wang

A paper, Honorifics without [HON], by 4th year student Ruoan Wang, has been accepted for publication in Natural Language & Linguistic Theory! Huge congratulations to Ruoan!
 
Manuscript here: https://ling.auf.net/lingbuzz/006802
 
Abstract:
Honorifics are grammaticalized reflexes of politeness, often recruiting existing featural values (e.g. French recruits plural ‘vous’ for polite address, and German third person plural ‘Sie’). This paper aims to derive their cross-linguistic distribution and interpretation without [HON], an analytical feature present since Corbett (2000). The striking generalization that emerges from a cross-linguistic survey of 120 languages is that only certain featural values are ever recruited for honorification: plural, third person, and indefinite. I show that these values are precisely those which are semantically unmarked, or presuppositionless, allowing the speaker to consider an interlocutor’s negative face (Brown & Levinson 1987). I propose an alternative analysis based on the interaction between semantic markedness, an avoidance-based pragmatic maxim called the Taboo of Directness, and Maximize Presupposition! (Heim 1991) to derive honorific meaning.

Industry workshop 10/12 - Ruth Brillman

The “careers for linguists” workshop will host our very own Ruth Brillman (PhD 2017), who is currently an engineering manager for Google Search and works right around the corner from us. She’ll join us in person for a Q&A about her path to industry.

When: Wednesday, 10/12, 2-3:30pm
Where: 32-D461 or on zoom (email me for a link)

Here is a short blurb from Ruth:

“I graduated from MIT with a PhD in Linguistics in 2017, where I specialized in syntax (primarily) and language acquisition. I’ve spent the past five years in industry, mostly working on NLP projects and building software informed by a structural understanding of language. Currently, I’m a software engineer at Google where I lead a small team focused on improving Google Search quality in lower-resource languages.”

New article in L&P — Aravind, Fox and Hackl

A new paper, Principles of presupposition in development, by Athulya Aravind, Danny Fox and Martin Hackl is just out in Linguistics & Philosophy! https://link.springer.com/article/10.1007/s10988-022-09364-z
 

LingLunch 10/13: Meg Gotowski (MIT) and Kristen Syrett (Rutgers)

Speakers: Meg Gotowski (MIT) & Kristen Syrett (Rutgers)

Time: Thursday 10/13, 12:30-1:50pm

Zoom link: https://mit.zoom.us/j/96548700087

In-person location: 32-D461

Title: It is daxy to learn adjectives, and learning adjectives is daxy for everyone: Syntactic frames support the acquisition of adjective meaning.

Abstract: How do children learn the meaning of adjectives like fun or delicious? These are adjectives that are context-dependent and speaker-dependent, encoding both gradability and subjectivity. For this reason, subjective such as these adjectives pose a challenge for word learning, given that they do not have a fixed referent. An influential theory in the word learning literature is syntactic bootstrapping, which claims that learners recruit the syntactic environment in which a word is found in order to deduce its meaning (Landau & Gleitman 1985). While syntactic bootstrapping has been examined extensively in regard to verb learning (Gleitman 1990; Fisher 2002; Gleitman et al. 2005), adjectives have received considerably less attention—and previous studies have also conflated syntactic and semantic information (such as animacy, Becker et al. 2012). In this research, we focus on subjective adjectives as a case study for analyzing the influence of the syntax alone within the adjectival domain. We discuss the results of a word learning experiment modeled after the Human Simulation Paradigm (Gillette et al. 1999), during which participants were presented with a novel adjective in a set of syntactic frames. Each set of frames crucially reflected the unique distributional signature of five different subclasses of subjective adjectives (Bylinina 2014). Participants demonstrated a sensitivity to these frames, and reliably recruited the syntax in order to narrow down the potential meanings for the novel adjectives, offering responses consistent with the set of frames provided—while becoming increasingly confident in their responses after encountering the adjective across multiple frames.

Colloquium 10/14 - Magdalena Kaufmann (UConn)

Speaker: Magdalena Kaufmann (UConn)
Title: How to be impossible or remote
Time:
Friday October 14, 3:30pm

Abstract: Natural languages mark so-called subjunctive conditionals that allow speakers to specify consequences of states of affairs they present as unlikely or counterfactual. Different morphosyntactic strategies within and across languages show what often seem to be idiosyncratic interactions between temporal and modal information. Building on in-depth studies of individual languages and more fine-grained distinctions between types of hypotheticality, the recent literature sees a trend towards a distinction between unrealized past possibilities and co-temporal counterfactual states of affairs.

In this talk, I draw on novel data from Serbian (joint work with Neda Todorović) and German in comparison to English and Japanese (joint work with Stefan Kaufmann), to support this idea and develop a compositional analysis.

LF Reading Group 10/12 - Keely New (MIT)

We’re excited to welcome Keely at the first LFRG of the semester! The meeting will be in person, but we’ll set up OWL for people in the department who want to attend virtually.

Zoom link: https://mit.zoom.us/j/94298987190​
Speaker: Keely New (MIT)
Time: Wednesday 10/12, 1-2pm
In-person location: 32-D461

Title: Associative plurals and the plural pronoun construction

Abstract: In Burmese, a conjunction of associative plural DPs has an available reading where the named individuals in the conjunction internally satisfy the plural requirement. I call this the internal plural reading. The internal plural reading is reminiscent of what has been called the plural pronoun construction in Russian, Greek etc. In this talk, I present a post-suppositional semantics for Burmese associative plurals. In a nutshell, I propose that the named individuals in a conjunction of associative plurals can satisfy each other’s plural requirement if the associative plural has a meaning that is post-suppositional. I discuss the extent to which this post-suppositional analysis can be extended to the PPC, particularly in light of the empirical landscape regarding the availability of PPC and internal plural reading across and within languages.​

Exp/Comp Group 10/14 - Nur Lan (École Normale Supérieure and Tel Aviv University)

Exp/Comp Group (10/14, 2-3:30pm)
Speaker: Nur Lan (École Normale Supérieure in Paris and Tel Aviv University)
Title: Minimum Description Length Recurrent Neural Networks
Location: 8th floor conference room, 32-D831
 
Nur will be giving a talk on his recent paper on neural networks (find it here: https://direct.mit.edu/tacl/article/doi/10.1162/tacl_a_00489/112499/Minimum-Description-Length-Recurrent-Neural). Everyone welcome!
 

Roger Paul, SM ‘20: statement for Indigenous Peoples’ Day 2022

From the MIT front page, October 10, 2022 — Indigenous Peoples’ Day:

“The MIT Indigenous Languages Initiative provides tools to help graduates keep their communities’ threatened languages alive. For Indigenous Peoples’ Day, Roger Paul  (SM ’20) penned this expression of gratitude in Passamaquoddy, around the MIT theme of “mind, hand, and heart.”


Benbaji and Pesetsky at virtual ellipsis seminar

Fourth-year student Ido Benbaji and faculty colleague David Pesetsky presented a joint paper entitled “E-Extension and the Uniformity of Silence” at the international online You’re on Mute workshop on ellipsis last Friday (co-organized by Gary Thoms (NYU) and Danfeng Wu (PhD 2022)).

Welcome to visiting faculty and postdocs!

Welcome to visiting faculty and postdocs!
 
Will Oxford (co-teaching 24.955 More Advanced Syntax with Sabine Iatridou): I’m visiting from the University of Manitoba, where I am an Associate Professor in the Department of Linguistics. I do theoretical and descriptive research on syntax and morphology, usually involving the Algonquian languages and often from a comparative perspective, with an emphasis on agreement and morphosyntactic alignment. My recent work has focused on the Algonquian direct-inverse system and its theoretical implications.
 
Forrest Davis (teaching 24.S96 Special Seminar: Methods in Computational Linguistics): Forrest Davis is a computational linguist and a new Postdoctoral Associate in the department. He received his PhD from Cornell’s Department of Linguistics this past summer. His work uses mismatches between neural network models and humans as a methodology for identifying systematic differences between linguistic experience and human linguistic knowledge. This fall, he is teaching a graduate seminar on building and interpreting neural models of language.
 
Giorgio Magri (teaching 24.964 Topics in Phonology): I graduated from the department in 2009. I have been living in Paris since then, where I work for the CNRS. During graduate school and shortly after, I have worked on semantics and pragmatics (scalar implicatures, genericity). Then, my research interests have switched to phonology. In the last few years, I have worked on probabilistic phonology. The goal is to understand how to do good phonology when the grammars are complex probability distributions. What is a probabilistic phonological analysis? What are the universals of a probabilistic typology? How can we distill the phonological predictions of a probabilistic framework? 
 
Ksenia Ershova (co-teaching 24.951 Introduction to Syntax  with David Pesetsky) I am a syntactician and fieldworker and a new Postdoctoral Associate in the department. I got my PhD from the University of Chicago in 2019 and was a postdoc at Stanford University before coming here. My work focuses on argument alignment, rules of word formation in polysynthesis, and wh-movement. Most of my research is based on fieldwork data from West Circassian and Samoan.
 
Megan Gotowski: Hi! My name is Meg Gotowski and I am a new postdoc working with Athulya Aravind in the Language Acquisition Lab. I recently graduated from Rutgers University, and moved here from Philadelphia. My research interests are in first language acquisition, syntax, semantics, and learnability theory. My dissertation focused specifically on word learning, and the role of syntactic bootstrapping in learning adjectives. When I am not doing research, I am usually running. I am a competitive long distance runner, as well as an avid rock climber and yogi.
 

Welcome to visiting students!

Welcome to visiting students Janek Guerrini, Elham Mehr, and Nur Lan!

Janek Guerrini: I am a PhD student in linguistics and philosophy at Institut Jean Nicod, at Ecole Normale Supérieure in Paris, working under the supervision of Benjamin Spector. I specialize in semantics and philosophy of language, and my main research interests are non-intersective modification and genericity. Here’s why I think they’re interesting: both of these phenomena have posed a long-standing challenge to semantic theory, and both seem to be particularly sensitive to the structure of our conceptual, non-linguistic representations. This makes for a domain where the study of language can both illuminate and be illuminated by broader questions in cognitive science. Most recently, I have been looking at some generic readings of indefinites in constructions we use to talk about similarity, as in “look like a lawyer”, which are puzzling because they do not seem to be reducible to an adverbial notion of genericity. 

Elham Mehr

Nur Lan: I’m a visiting PhD student from ENS Paris, co-advised by Emmanuel Chemla (ENS) and Roni Katzir (Tel Aviv University). I originally studied computer science and I like to build models of language learning.

Syntax Square 10/4 - Giovanni Roversi (MIT)

Speaker: Giovanni Roversi (MIT)
Title: Where can probes be? Evidence from asymmetric adjectival concord
Time: Tuesday, October 4th, 1pm - 2pm

Abstract: We currently don’t have a theory telling us what kind of probes should or shouldn’t be where; I’m not going to propose one either. In this talk I will make an indirect argument for not wanting too restrictive a theory: the empirical landscape, when looked at carefully, is too varied for us to be able to afford a restrictive theory of probe distribution. The domain I will concentrate on is asymmetric adjectival concord, that is, languages where the morphological patterns on attributive adjectives and predicative ones (“the red car” vs “the car is red”) are different. I will try to convince you that the typology of attested patterns does in fact cover all logically possible asymmetries, so that our theory should be able to derive all of them.

Experimental/Computational Ling Group 9/30 - Meg Gotowski and Forrest Davis (MIT)

Meg Gotowski and Forrest Davis will be giving presentations on their dissertation research. Join us on Friday (9/30) from 2-3:30 in the 8th floor conference room (32-D831). 


It is DAXY to learn! Bootstrapping in the Adjectival Domain (Meg Gotowski) 

Abstract: An influential theory in word learning is known as syntactic bootstrapping (Landau & Gleitman 1985), which claims that children are able to map structure to meaning.  Most of the bootstrapping literature has focused on the ability of learners to rely on syntactic frames in order to deduce the meaning of verbs (see Gleitman et al. 2005). In this talk, I examine how syntactic bootstrapping extends to the adjectival domain, focusing on how learners are able to acquire different subclasses of subjective gradable predicates (e.g. fun, tasty, tough). I discuss the results of an experiment based on the Human Simulation Paradigm (Gillette et al. 1999), and argue that while learners are sensitive to individual adjectival frames, they are also dependent on seeing adjectives across multiple frames in order to effectively narrow down the hypothesis space of possible meanings (consistent with Mintz 2003 for verbs).  


Neural Models of Language and the Limits of Superficialism (Forrest Davis) 

Abstract: A typical approach to evaluating neural models of language for linguistic knowledge will find instances of overlap between humans and models. This overlap is claimed to be evidence that our linguistic theories can be simplified. I will instead argue for a different approach to evaluating such models. I advance the position that neural models are models of “superficialism”, the worldview which asserts that all meaningful linguistic (and more broadly psychological) distinctions can be made on the basis of observing ordinary behavior. By assuming this worldview, the role of data in determining a neural model’s behavior is centered. I then show via two case studies (ambiguous relative clause attachment and implicit causality) that mismatches between neural models and humans follow from general properties of data. I conclude by suggesting that, to the extent that these really are general properties of data, models will always be sensitive to incorrect generalizations. 

MIT @ SuB27!

MIT had a huge turnout at Sinn und Bedeutung 27 in Prague, 14-16 September 2022! 


Current students:

+ Lorenzo Pinton (with Maria Aloni): Sluicing and Free Choice
+ Adèle Hénot-Mortier: A dynamic alternative-pruning account of asymmetries in Hurford disjunctions
+ Ido Benbaji: (with Omri) Adversative only is only only; (with Yash and Filipe) The Logic of Hindi Co-compounds
+ Enrico Flor: Questions in non-distributive belief ascriptions
+ Jad Wehbe: Against the lexical view of cumulative inferences and homogeneity
+ Omri Doron: (with Ido) Adversative only is only only
+ Anastasia Tsilia (poster): “Quasi-ECM” constructions in Modern Greek: Evidence for semantic lowering

Alums:

+ Itai Bassi: Strict readings of logophors and the LF of anaphoric dependencies (with others) 
+ Jonathan Bobaljik: (with Uli Sauerland) About ‘us’
+ Uli Sauerland (invited): An Algebra of Thought that Predicts Key Aspects of Language Structure; (with Jonathan Bobaljik) About ‘us’
+ Pritty Patel-Grosz (invited): The search for universal primate gestural meanings
+ Yasutada Sudo: Against simplification: free choice with anaphora
+ Sam Alxatib: Necessary Free Choice and its theoretical significance

Presenting but not in the picture:

+ İsa Kerem Bayırlı (alumnus): UM2: A Generalization over Determiner Denotations
+ Yash Sinha (with Ido and Filipe): The Logic of Hindi Co-compounds
+ Filipe Hisao Kobayashi (with Ido and Yash): The Logic of Hindi Co-compounds

Industry workshop 9/28 - Andy Zhang

Who: Dr. Andy Zhang (Analytical Linguist at Google, virtual talk)
When: Wednesday 9/28 2-2:45
Where: 5-231 or on zoom (contact Hadas Kotek for the link)
What: Andy is a linguist(/data scientist/PM) at Google. His team works on designing and building machine learning systems that protect kids’ safety on Google surfaces across the internet. Andy’s particular domain is designing ML systems for enhancing the safety of ads that serve in Search for underage users. Andy completed his PhD in linguistics at Yale in 2021, where his work focused on how the ways in which we are different (domain-general dimensions of individual-level cognitive variability) influence and constrain (a) the ways in which we use language (real-time comprehension, lexical semantics) and (b) the ways in which languages change over time (diachronic semantics, grammaticalization pathways). 
 
Andy writes: “I’m looking forward to sharing about my journey into tech and hopefully helping you out on yours!”

Syntax Square 9/27 - Peter Grishin (MIT)

Speaker: Peter Grishin (MIT)
Title: Passamaquoddy subordinative clauses are TPs
Time: Tuesday, September 27th, 1pm - 2pm

Abstract: Algonquian languages are known for their distinct inflectional paradigms that have different syntactic distributions, something that has received quite a bit of interest in the theoretical literature (Campana 1996, Brittain 2001, Richards 2004, Cook 2014, Bogomolets, Fenger, and Stegovec 2022, a.o.). However, one inflectional paradigm/clause type has not received much (if any) attention: the subordinative, an Eastern Algonquian innovation. In this talk I’ll present some fieldwork and corpus data on the subordinative in Passamaquoddy, proposing that the seemingly-unrelated syntactic contexts it appears in—clausal complements to certain verbs and modal particles, some clausal coordinations, and polite imperatives—can all be unified if we take subordinative clauses to be TP sized, lacking a CP layer. While I think the broad picture I sketch is compelling, there are some loose ends and problems that will emerge—I’m looking for help with figuring out how to deal with them.

LSA ballot open until November 5

The annual ballot of the Linguistic Society of America is now open and members have until November 5, 2022 to cast their votes. There are a series of proposed amendments to the LSA Constitution and Bylaws and the LSA’s website provides some comments from members pro and contra. The ballot also includes the slate of candidates for various positions in the Society:

  • Marlyse Baptista (University of Michigan) for
    Vice-President/President Elect
  • Shelome Gooden (University of Pittsburgh) for Language
    Co-Editor
  • Four candidates for two at-large seats on the Executive Commitee:
    • Melissa Baese-Berk (University of Oregon)
    • Michel DeGraff (Massachusetts Institute of Technology)
    • Sali A. Tagliamonte (University of Toronto)
    • Michal Temkin Martinez (Boise State University)

LingLunch 9/29 - Janek Guerrini (Institut Jean Nicod, ENS)

Speaker: Janek Guerrini (Institut Jean Nicod, ENS)
Title: Genericity in similarity
Time: Thursday, September 29th, 12:30pm - 1:50pm

Abstract: In this talk, I offer an account of similarity constructions involving ‘like’, such as ‘be like’ and ‘look like’. I argue that these constructions have two key properties. (1) The first is that similarity predication amounts to predication of overlap of salient properties: I analyse ‘John is like Mary’ as ‘John shares relevant properties with Mary’. This is motivated by the fact that there seem to be grammatical devices that single out precisely what properties are relevant, e.g. ‘With respect to personality, she’s just like her father’. (2) The second key feature of similarity talk is, I argue, that it involves inherent generic quantification. This explains a range of data: first, it accounts for the reading of indefinites embedded in ‘like’ Prepositional Phrases: ‘John looks like a lawyer’ is almost equivalent to ‘John looks like a typical lawyer’. Second, it accounts for narrow-scope and almost conjunctive readings of disjunction in the scope of ‘like’: ‘Mary looks like a lawyer or a judge’ is almost equivalent (on its most accessible reading) to ‘Mary looks like a lawyer and Mary looks like a judge’.